August 2025
103 posts: 11 entries, 47 links, 21 quotes, 6 notes, 13 beats, 5 newsletters
Sunday, 24th August 2025
Static Sites with Python, uv, Caddy, and Docker (via) Nik Kantar documents his Docker-based setup for building and deploying mostly static web sites in line-by-line detail.
I found this really useful. The Dockerfile itself without comments is just 8 lines long:
FROM ghcr.io/astral-sh/uv:debian AS build
WORKDIR /src
COPY . .
RUN uv python install 3.13
RUN uv run --no-dev sus
FROM caddy:alpine
COPY Caddyfile /etc/caddy/Caddyfile
COPY --from=build /src/output /srv/
He also includes a Caddyfile that shows how to proxy a subset of requests to the Plausible analytics service.
The static site is built using his sus package for creating static URL redirecting sites, but would work equally well for another static site generator you can install and run with uv run.
Nik deploys his sites using Coolify, a new-to-me take on the self-hosting alternative to Heroku/Vercel pattern which helps run multiple sites on a collection of hosts using Docker containers.
A bunch of the Hacker News comments dismissed this as over-engineering. I don't think that criticism is justified - given Nik's existing deployment environment I think this is a lightweight way to deploy static sites in a way that's consistent with how everything else he runs works already.
More importantly, the world needs more articles like this that break down configuration files and explain what every single line of them does.
Monday, 25th August 2025
Agentic Browser Security: Indirect Prompt Injection in Perplexity Comet. The security team from Brave took a look at Comet, the LLM-powered "agentic browser" extension from Perplexity, and unsurprisingly found security holes you can drive a truck through.
The vulnerability we’re discussing in this post lies in how Comet processes webpage content: when users ask it to “Summarize this webpage,” Comet feeds a part of the webpage directly to its LLM without distinguishing between the user’s instructions and untrusted content from the webpage. This allows attackers to embed indirect prompt injection payloads that the AI will execute as commands. For instance, an attacker could gain access to a user’s emails from a prepared piece of text in a page in another tab.
Visit a Reddit post with Comet and ask it to summarize the thread, and malicious instructions in a post there can trick Comet into accessing web pages in another tab to extract the user's email address, then perform all sorts of actions like triggering an account recovery flow and grabbing the resulting code from a logged in Gmail session.
Perplexity attempted to mitigate the issues reported by Brave... but an update to the Brave post later confirms that those fixes were later defeated and the vulnerability remains.
Here's where things get difficult: Brave themselves are developing an agentic browser feature called Leo. Brave's security team describe the following as a "potential mitigation" to the issue with Comet:
The browser should clearly separate the user’s instructions from the website’s contents when sending them as context to the model. The contents of the page should always be treated as untrusted.
If only it were that easy! This is the core problem at the heart of prompt injection which we've been talking about for nearly three years - to an LLM the trusted instructions and untrusted content are concatenated together into the same stream of tokens, and to date (despite many attempts) nobody has demonstrated a convincing and effective way of distinguishing between the two.
There's an element of "those in glass houses shouldn't throw stones here" - I strongly expect that the entire concept of an agentic browser extension is fatally flawed and cannot be built safely.
One piece of good news: this Hacker News conversation about this issue was almost entirely populated by people who already understand how serious this issue is and why the proposed solutions were unlikely to work. That's new: I'm used to seeing people misjudge and underestimate the severity of this problem, but it looks like the tide is finally turning there.
Update: in a comment on Hacker News Brave security lead Shivan Kaul Sahib confirms that they are aware of the CaMeL paper, which remains my personal favorite example of a credible approach to this problem.
Tuesday, 26th August 2025
Will Smith’s concert crowds are real, but AI is blurring the lines. Great piece from Andy Baio demonstrating quite how convoluted the usage ethics and backlash against generative AI has become.
Will Smith has been accused of using AI to misleadingly inflate the audience sizes of his recent tour. It looks like the audiences were real, but the combined usage of static-image-to-video models by his team with YouTube's ugly new compression experiments gave the resulting footage an uncanny valley effect that lead to widespread doubts over the veracity of the content.
Piloting Claude for Chrome. Two days ago I said:
I strongly expect that the entire concept of an agentic browser extension is fatally flawed and cannot be built safely.
Today Anthropic announced their own take on this pattern, implemented as an invite-only preview Chrome extension.
To their credit, the majority of the blog post and accompanying support article is information about the security risks. From their post:
Just as people encounter phishing attempts in their inboxes, browser-using AIs face prompt injection attacks—where malicious actors hide instructions in websites, emails, or documents to trick AIs into harmful actions without users' knowledge (like hidden text saying "disregard previous instructions and do [malicious action] instead").
Prompt injection attacks can cause AIs to delete files, steal data, or make financial transactions. This isn't speculation: we’ve run “red-teaming” experiments to test Claude for Chrome and, without mitigations, we’ve found some concerning results.
Their 123 adversarial prompt injection test cases saw a 23.6% attack success rate when operating in "autonomous mode". They added mitigations:
When we added safety mitigations to autonomous mode, we reduced the attack success rate of 23.6% to 11.2%
I would argue that 11.2% is still a catastrophic failure rate. In the absence of 100% reliable protection I have trouble imagining a world in which it's a good idea to unleash this pattern.
Anthropic don't recommend autonomous mode - where the extension can act without human intervention. Their default configuration instead requires users to be much more hands-on:
- Site-level permissions: Users can grant or revoke Claude's access to specific websites at any time in the Settings.
- Action confirmations: Claude asks users before taking high-risk actions like publishing, purchasing, or sharing personal data.
I really hate being stop energy on this topic. The demand for browser automation driven by LLMs is significant, and I can see why. Anthropic's approach here is the most open-eyed I've seen yet but it still feels doomed to failure to me.
I don't think it's reasonable to expect end users to make good decisions about the security risks of this pattern.
Wednesday, 27th August 2025
We simply don’t know to defend against these attacks. We have zero agentic AI systems that are secure against these attacks. Any AI that is working in an adversarial environment—and by this I mean that it may encounter untrusted training data or input—is vulnerable to prompt injection. It’s an existential problem that, near as I can tell, most people developing these technologies are just pretending isn’t there.
V&A East Storehouse and Operation Mincemeat in London
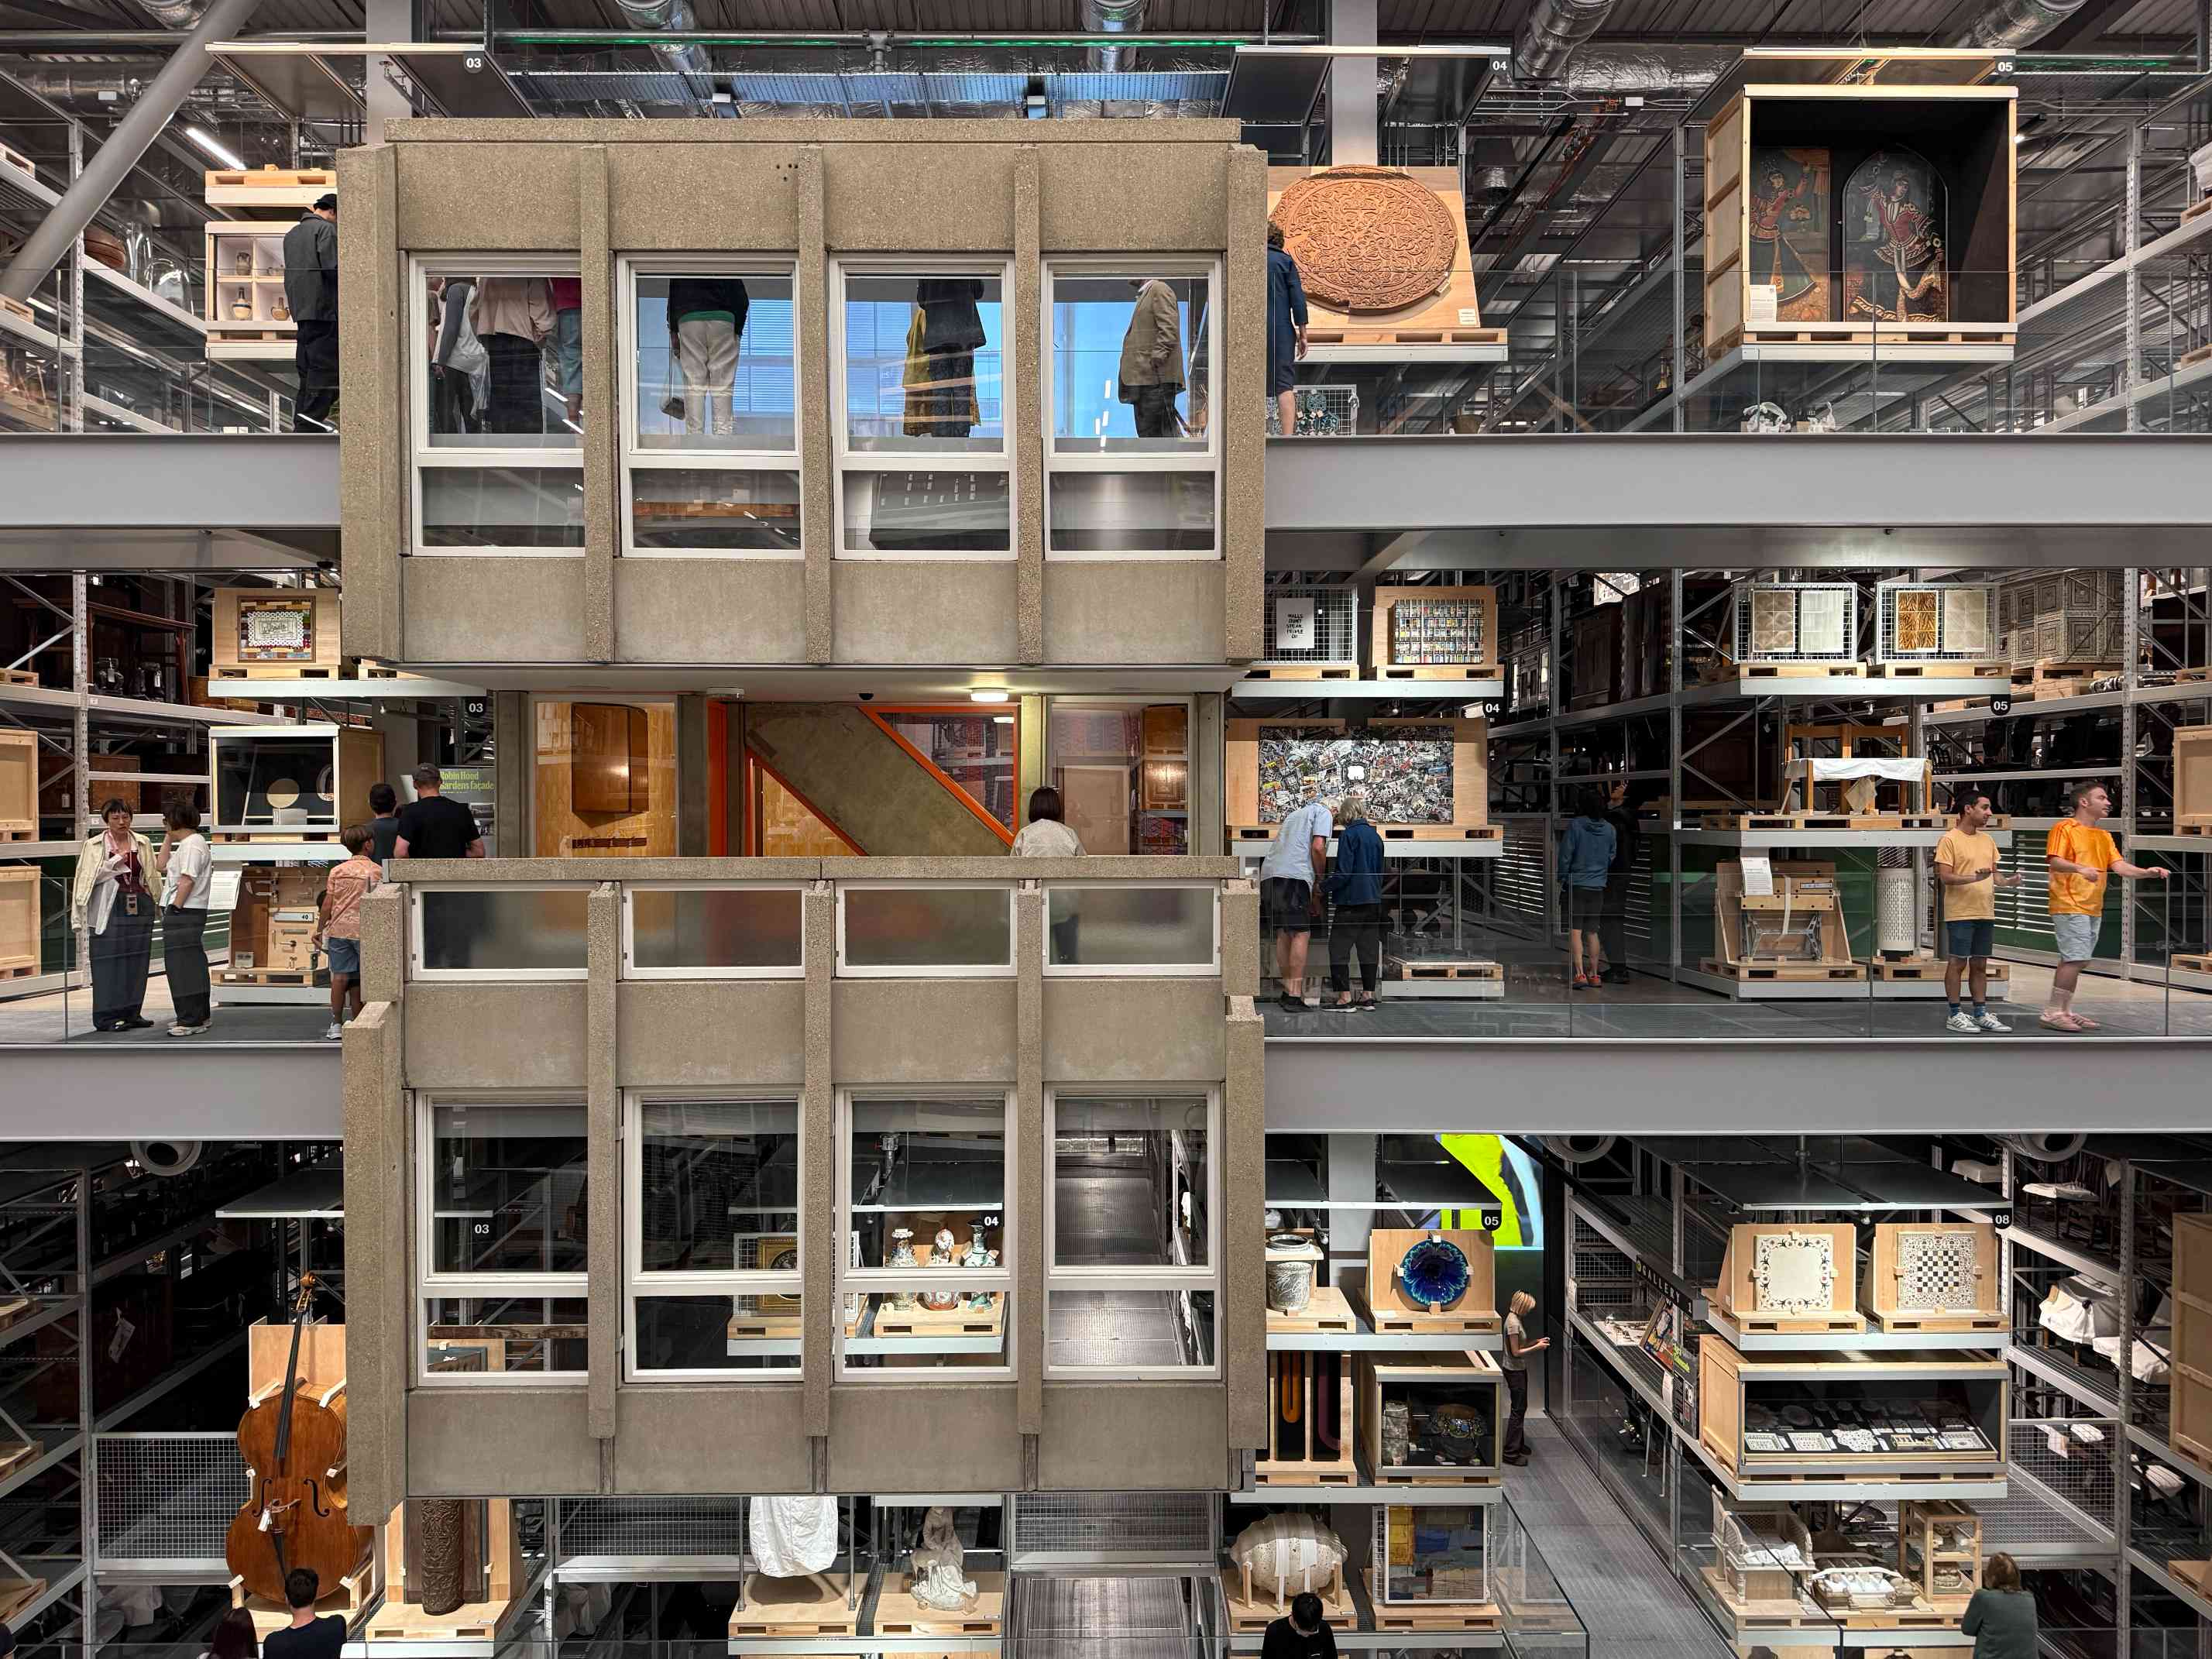
We were back in London for a few days and yesterday had a day of culture.
[... 481 words]Thursday, 28th August 2025
Python: The Documentary. New documentary about the origins of the Python programming language - 84 minutes long, built around extensive interviews with Guido van Rossum and others who were there at the start and during the subsequent journey.
Friday, 29th August 2025
Since I love collecting questionable analogies for LLMs, here's a new one I just came up with: an LLM is a lossy encyclopedia. They have a huge array of facts compressed into them but that compression is lossy (see also Ted Chiang).
The key thing is to develop an intuition for questions it can usefully answer vs questions that are at a level of detail where the lossiness matters.
This thought sparked by a comment on Hacker News asking why an LLM couldn't "Create a boilerplate Zephyr project skeleton, for Pi Pico with st7789 spi display drivers configured". That's more of a lossless encyclopedia question!
My answer:
The way to solve this particular problem is to make a correct example available to it. Don't expect it to just know extremely specific facts like that - instead, treat it as a tool that can act on facts presented to it.
The perils of vibe coding. I was interviewed by Elaine Moore for this opinion piece in the Financial Times, which ended up in the print edition of the paper too! I picked up a copy yesterday:

From the article, with links added by me to relevant projects:
Willison thinks the best way to see what a new model can do is to ask for something unusual. He likes to request an SVG (an image made out of lines described with code) of a pelican on a bike and asks it to remember the chickens in his garden by name. Results can be bizarre. One model ignored his prompts in favour of composing a poem.
Still, his adventures in vibe coding sound like an advert for the sector. He used Anthropic's Claude Code, the favoured model for developers, to make an OCR (optical character recognition - software loves acronyms) tool that will copy and paste text from a screenshot.
He wrote software that summarises blog comments and has plans to build a custom tool that will alert him when a whale is visible from his Pacific coast home. All this by typing prompts in English.
I've been talking about that whale spotting project for far too long. Now that it's been in the FT I really need to build it.
(On the subject of OCR... I tried extracting the text from the above image using GPT-5 and got a surprisingly bad result full of hallucinated details. Claude Opus 4.1 did a lot better but still made some mistakes. Gemini 2.5 did much better.)
Talk Python: Celebrating Django’s 20th Birthday With Its Creators. I recorded this podcast episode recently to celebrate Django's 20th birthday with Adrian Holovaty, Will Vincent, Jeff Triplet, and Thibaud Colas.
We didn’t know that it was a web framework. We thought it was a tool for building local newspaper websites. [...]
Django’s original tagline was ‘Web development on journalism deadlines’. That’s always been my favorite description of the project.
Saturday, 30th August 2025
LLMs are intelligence without agency—what we might call "vox sine persona": voice without person. Not the voice of someone, not even the collective voice of many someones, but a voice emanating from no one at all.
Claude Opus 4.1 and Opus 4 degraded quality. Notable because often when people complain of degraded model quality it turns out to be unfounded - Anthropic in the past have emphasized that they don't change the model weights after releasing them without changing the version number.
In this case a botched upgrade of their inference stack cause a genuine model degradation for 56.5 hours:
From 17:30 UTC on Aug 25th to 02:00 UTC on Aug 28th, Claude Opus 4.1 experienced a degradation in quality for some requests. Users may have seen lower intelligence, malformed responses or issues with tool calling in Claude Code.
This was caused by a rollout of our inference stack, which we have since rolled back for Claude Opus 4.1. [...]
We’ve also discovered that Claude Opus 4.0 has been affected by the same issue and we are in the process of rolling it back.