26th August 2026 - Link Blog
Qwen3.8-Flash-Next (via) Another open weights model from Qwen. This one is "a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4".
It's pretty big: 125B parameters but only 6B active which means it gets a significant performance boost.
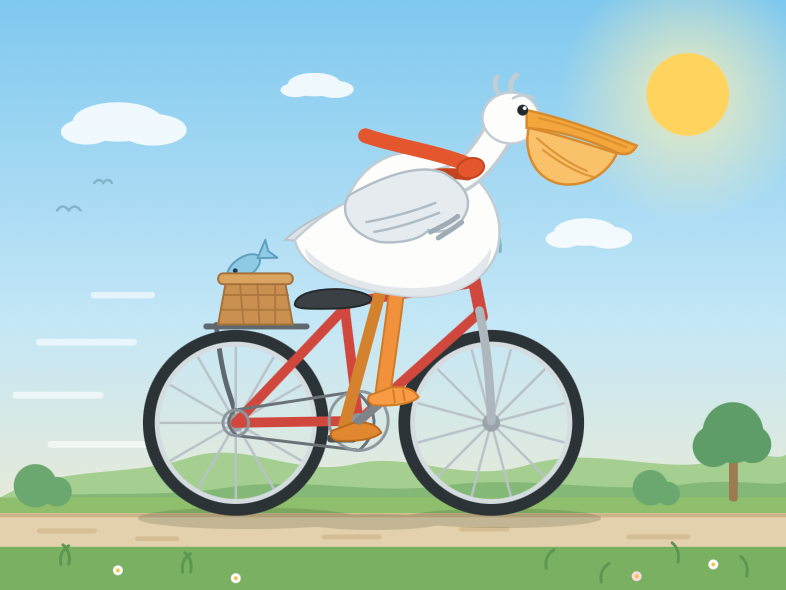
I've been trying it out on a DGX Spark using these Unsloth quantized models. I'm still exploring the model - so far I've tried the 72.5GB UD-IQ1_S one (producing these pelicans) and the 78.9GB UD-Q2_K_XL (producing these).
My favorite so far was this xhigh reasoning effort one from UD-Q2_K_XL:
Recent articles
- Hello Python 3.15, goodbye 3.10, and now I can use 3.11 - 12th October 2026
- A new feature for my blog, built using my voice - 9th October 2026
- Claude Haiku 5.5 - 7th October 2026
- We're going to need default hard budget caps on pretty much everything - 3rd October 2026