Entries
Filters: Sorted by date
Initial impressions of Llama 4
Dropping a model release as significant as Llama 4 on a weekend is plain unfair! So far the best place to learn about the new model family is this post on the Meta AI blog. They’ve released two new models today: Llama 4 Maverick is a 400B model (128 experts, 17B active parameters), text and image input with a 1 million token context length. Llama 4 Scout is 109B total parameters (16 experts, 17B active), also multi-modal and with a claimed 10 million token context length—an industry first.
[... 1,468 words]Putting Gemini 2.5 Pro through its paces
There’s a new release from Google Gemini this morning: the first in the Gemini 2.5 series. Google call it “a thinking model, designed to tackle increasingly complex problems”. It’s already sat at the top of the LM Arena leaderboard, and from initial impressions looks like it may deserve that top spot.
[... 2,400 words]New audio models from OpenAI, but how much can we rely on them?
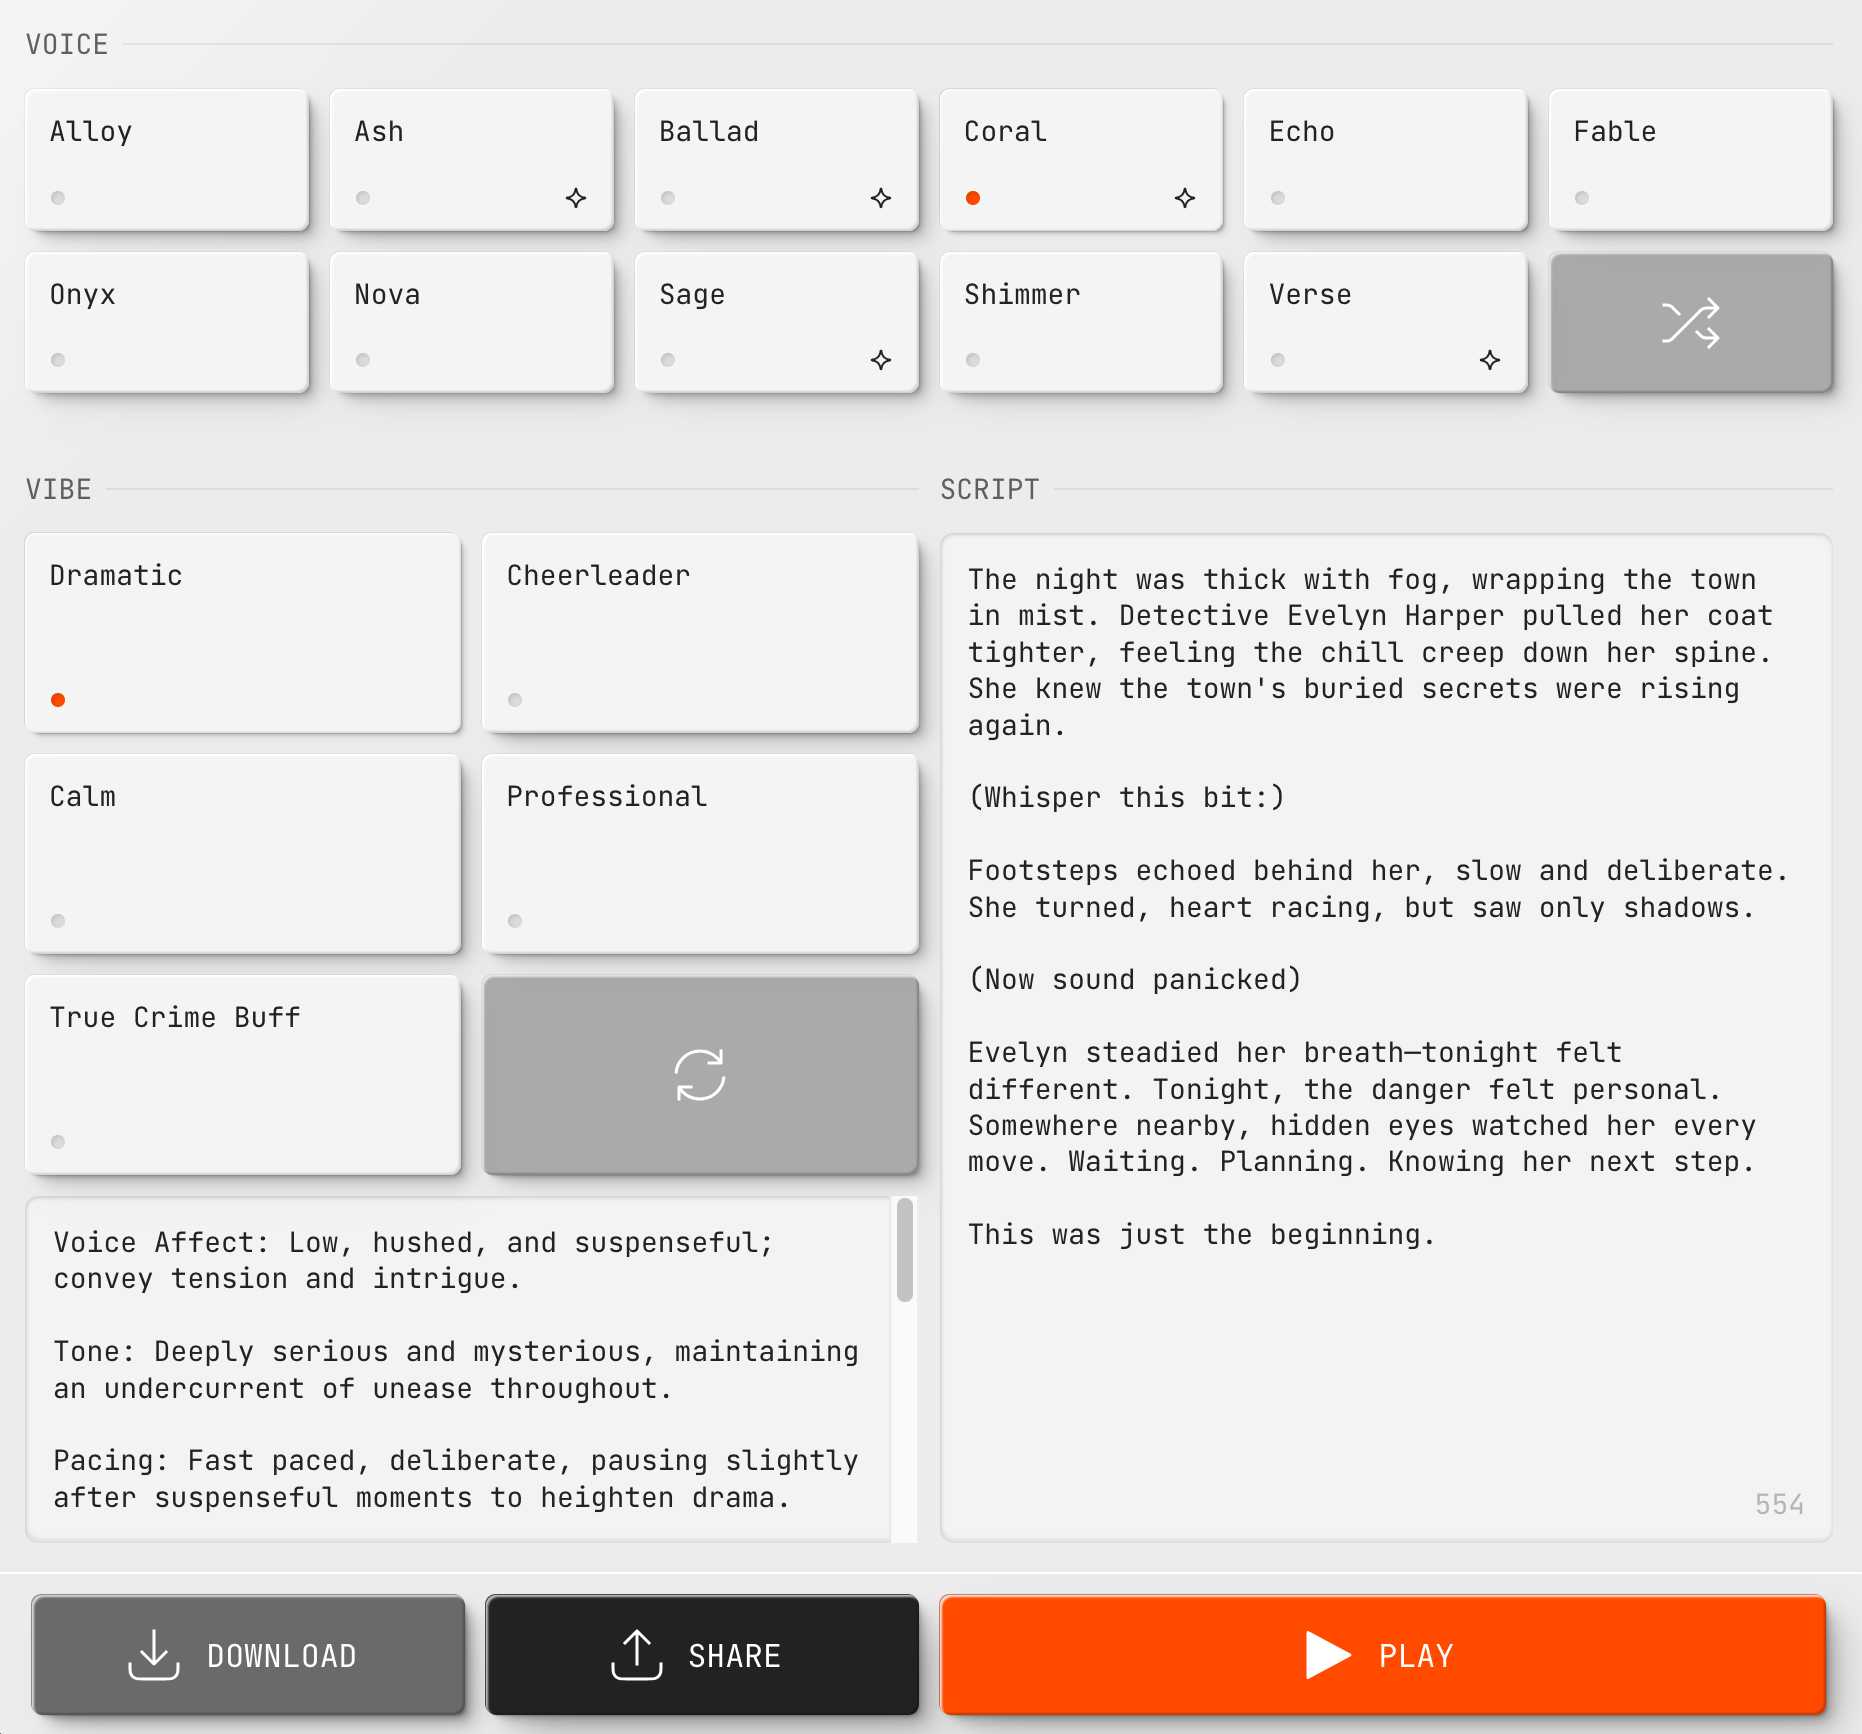
OpenAI announced several new audio-related API features today, for both text-to-speech and speech-to-text. They’re very promising new models, but they appear to suffer from the ever-present risk of accidental (or malicious) instruction following.
[... 866 words]Calling a wrap on my weeknotes
After 192 posts that ranged from weekly to roughly once-a-month, I’ve decided to call a wrap on my weeknotes habit. The original goal was to stay transparent during my 2019-2020 JSK fellowship, and I kept them up after that as an accountability mechanism and to get into a habit of writing regularly.
[... 281 words]Not all AI-assisted programming is vibe coding (but vibe coding rocks)
Vibe coding is having a moment. The term was coined by Andrej Karpathy just a few weeks ago (on February 6th) and has since been featured in the New York Times, Ars Technica, the Guardian and countless online discussions.
[... 1,486 words]Adding AI-generated descriptions to my tools collection
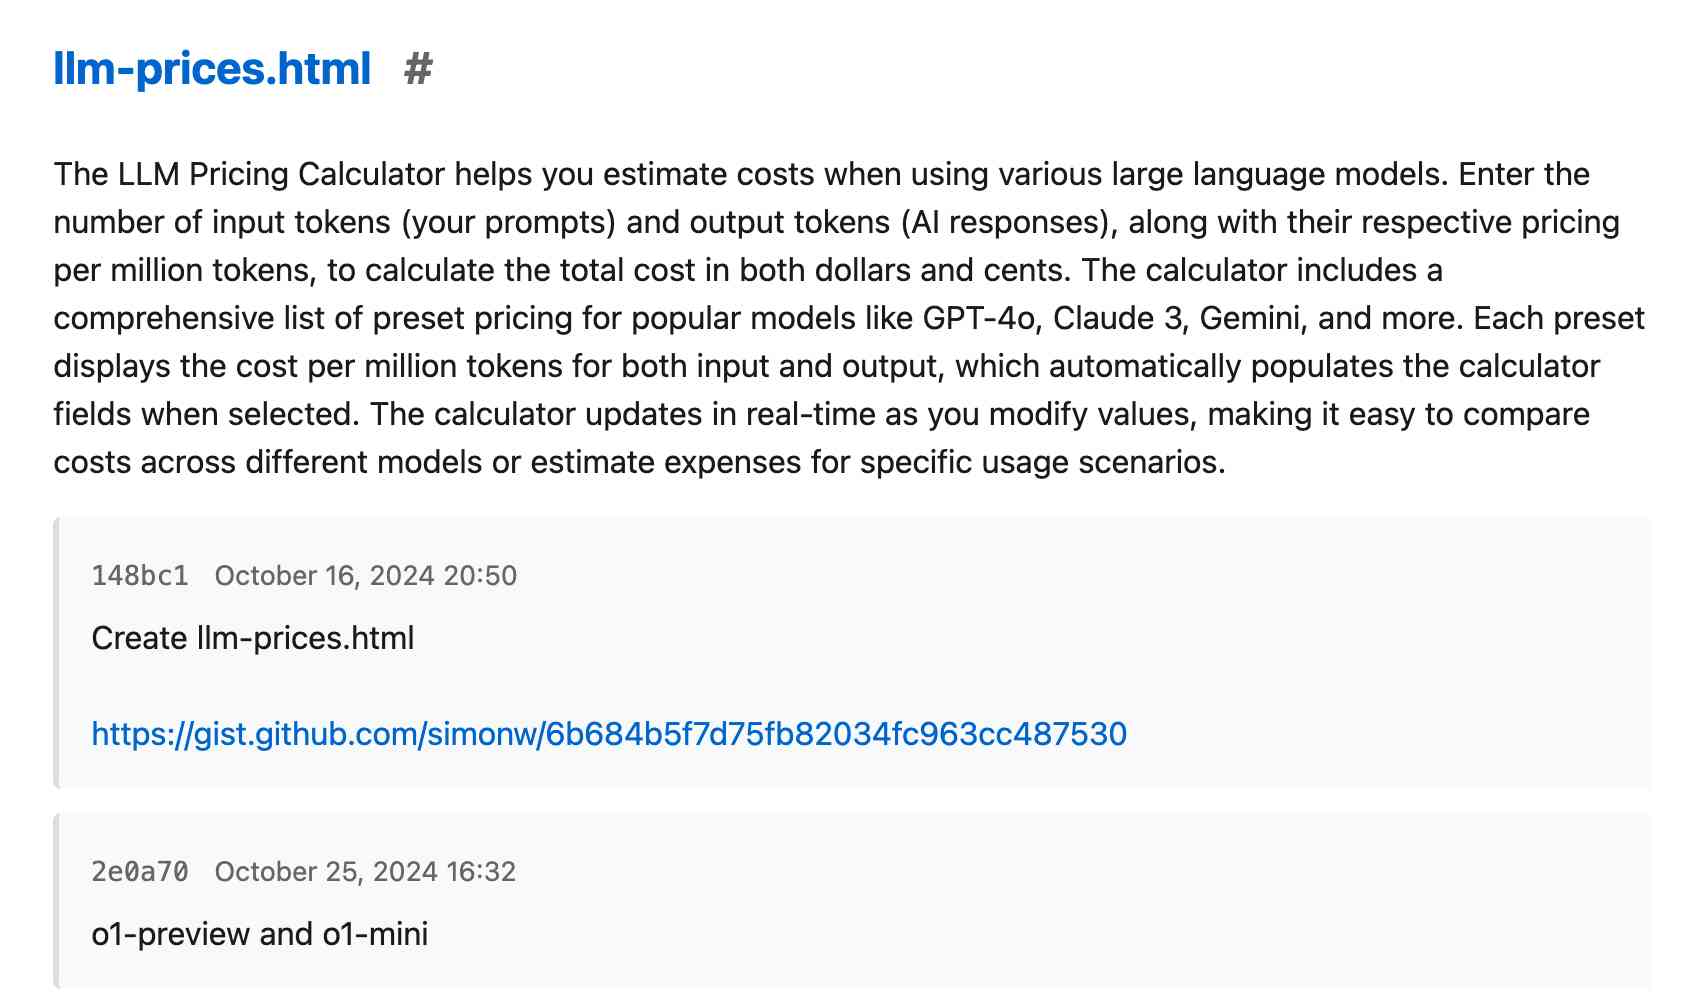
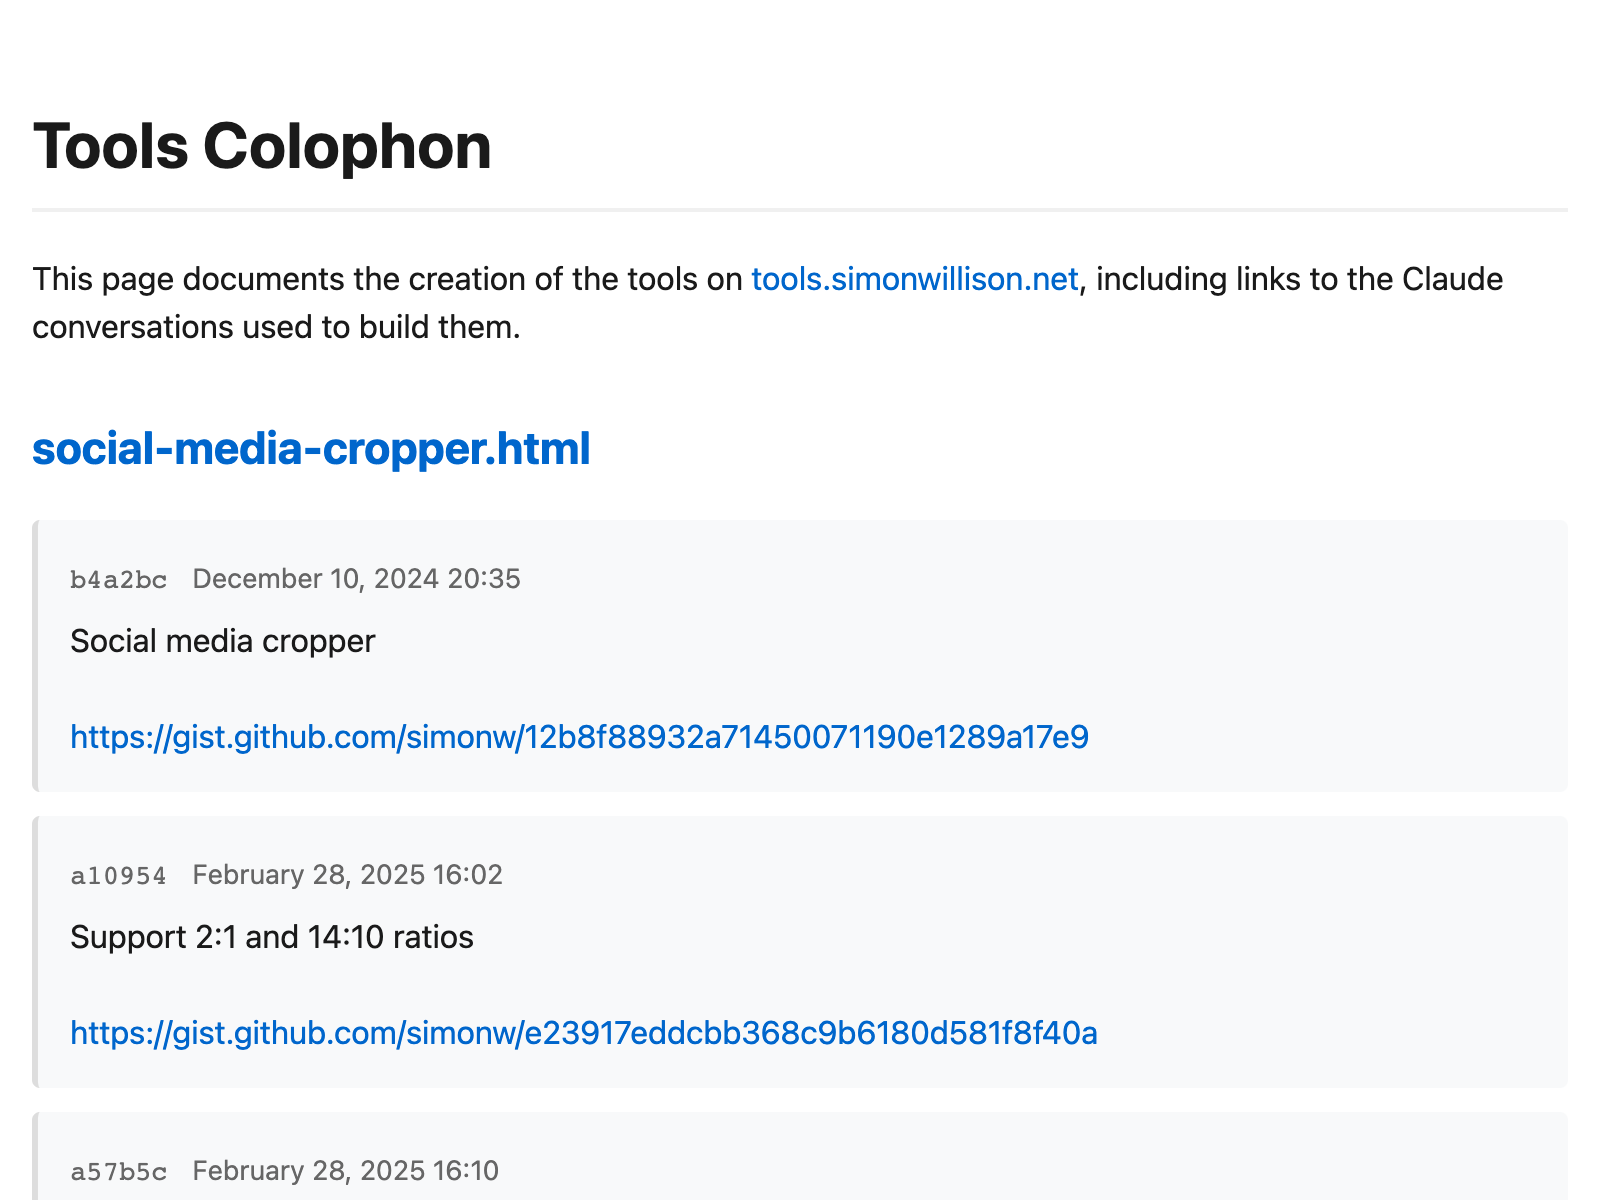
The /colophon page on my tools.simonwillison.net site lists all 78 of the HTML+JavaScript tools I’ve built (with AI assistance) along with their commit histories, including links to prompting transcripts. I wrote about how I built that colophon the other day. It now also includes a description of each tool, generated using Claude 3.7 Sonnet.
[... 741 words]Notes on Google’s Gemma 3
Google’s Gemma team released an impressive new model today (under their not-open-source Gemma license). Gemma 3 comes in four sizes—1B, 4B, 12B, and 27B—and while 1B is text-only the larger three models are all multi-modal for vision:
[... 804 words]Here’s how I use LLMs to help me write code
Online discussions about using Large Language Models to help write code inevitably produce comments from developers who’s experiences have been disappointing. They often ask what they’re doing wrong—how come some people are reporting such great results when their own experiments have proved lacking?
[... 5,178 words]What’s new in the world of LLMs, for NICAR 2025
I presented two sessions at the NICAR 2025 data journalism conference this year. The first was this one based on my review of LLMs in 2024, extended by several months to cover everything that’s happened in 2025 so far. The second was a workshop on Cutting-edge web scraping techniques, which I’ve written up separately.
[... 2,797 words]I built an automaton called Squadron
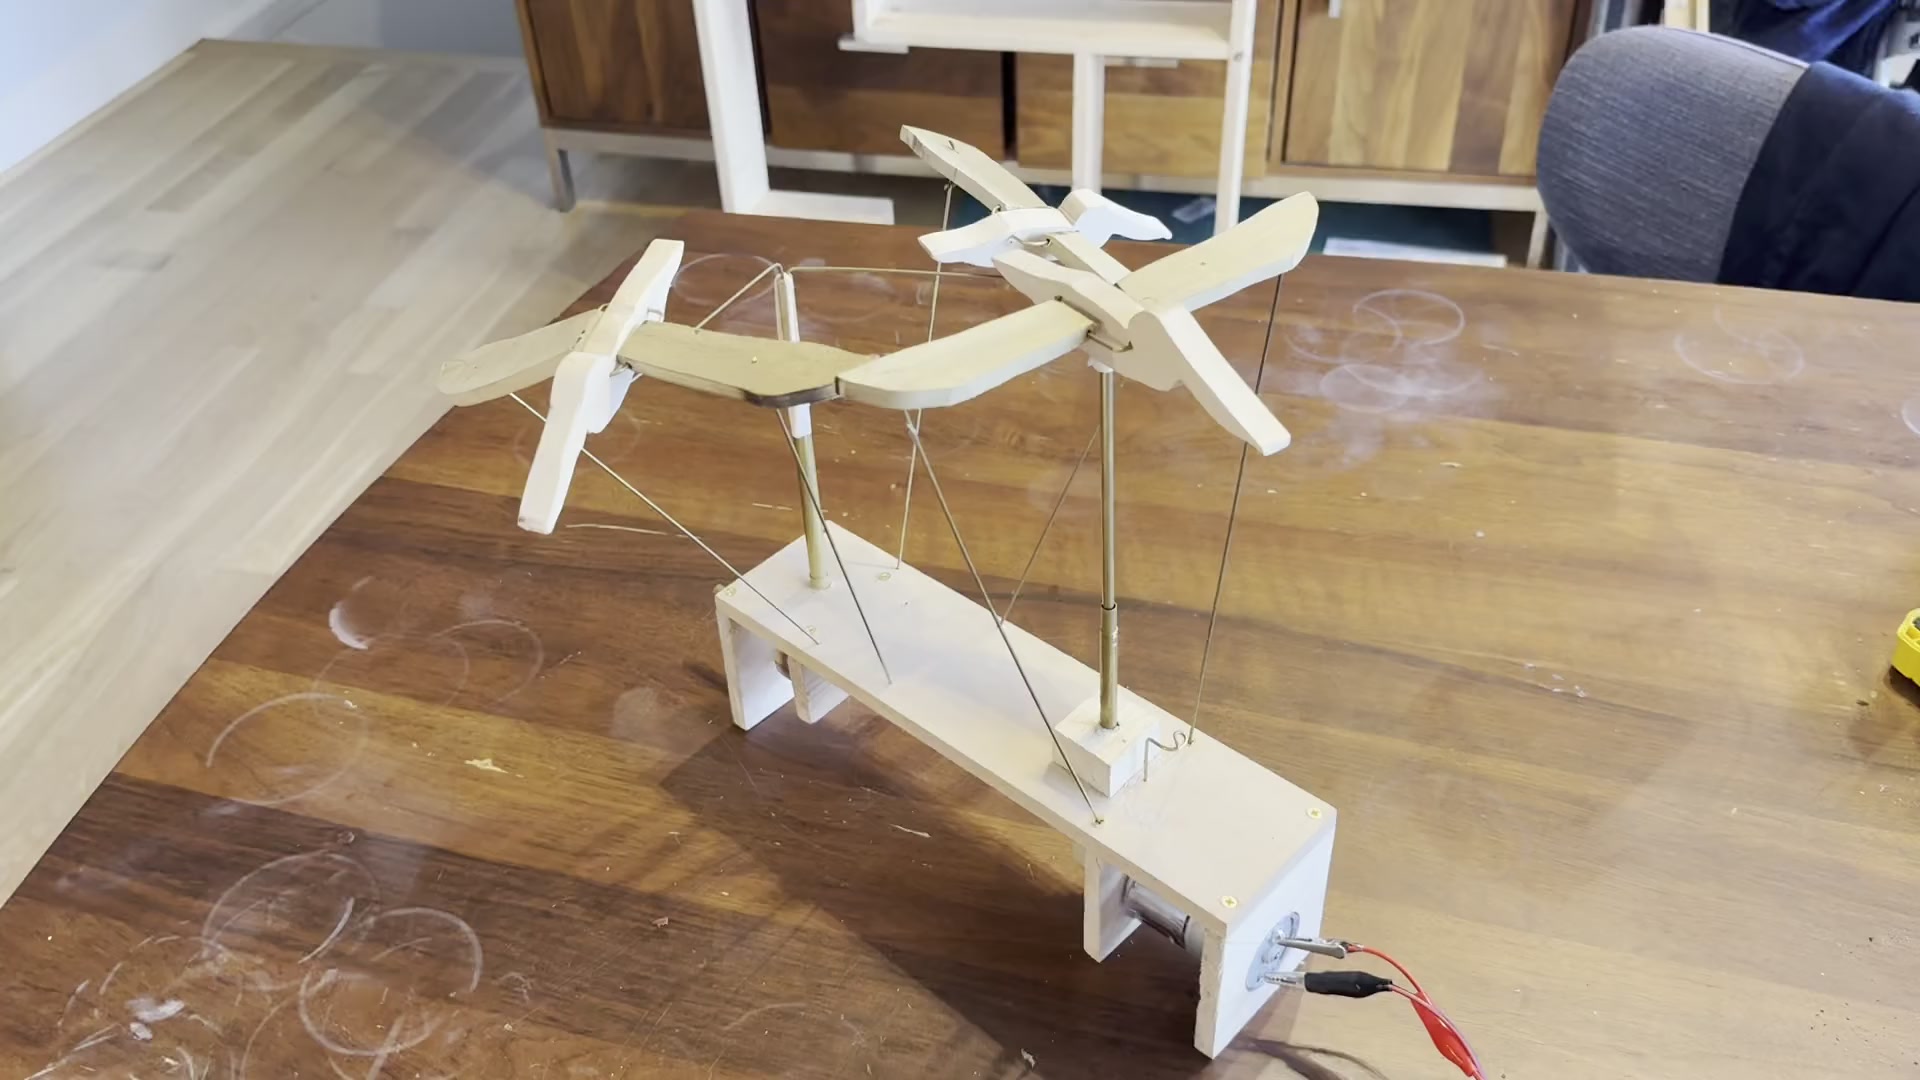
I believe that the price you have to pay for taking on a project is writing about it afterwards. On that basis, I feel compelled to write up my decidedly non-software project from this weekend: Squadron, an automaton.
[... 1,142 words]Notes from my Accessibility and Gen AI podcast appearance

I was a guest on the most recent episode of the Accessibility + Gen AI Podcast, hosted by Eamon McErlean and Joe Devon. We had a really fun, wide-ranging conversation about a host of different topics. I’ve extracted a few choice quotes from the transcript.
[... 947 words]Hallucinations in code are the least dangerous form of LLM mistakes
A surprisingly common complaint I see from developers who have tried using LLMs for code is that they encountered a hallucination—usually the LLM inventing a method or even a full software library that doesn’t exist—and it crashed their confidence in LLMs as a tool for writing code. How could anyone productively use these things if they invent methods that don’t exist?
[... 1,052 words]Structured data extraction from unstructured content using LLM schemas
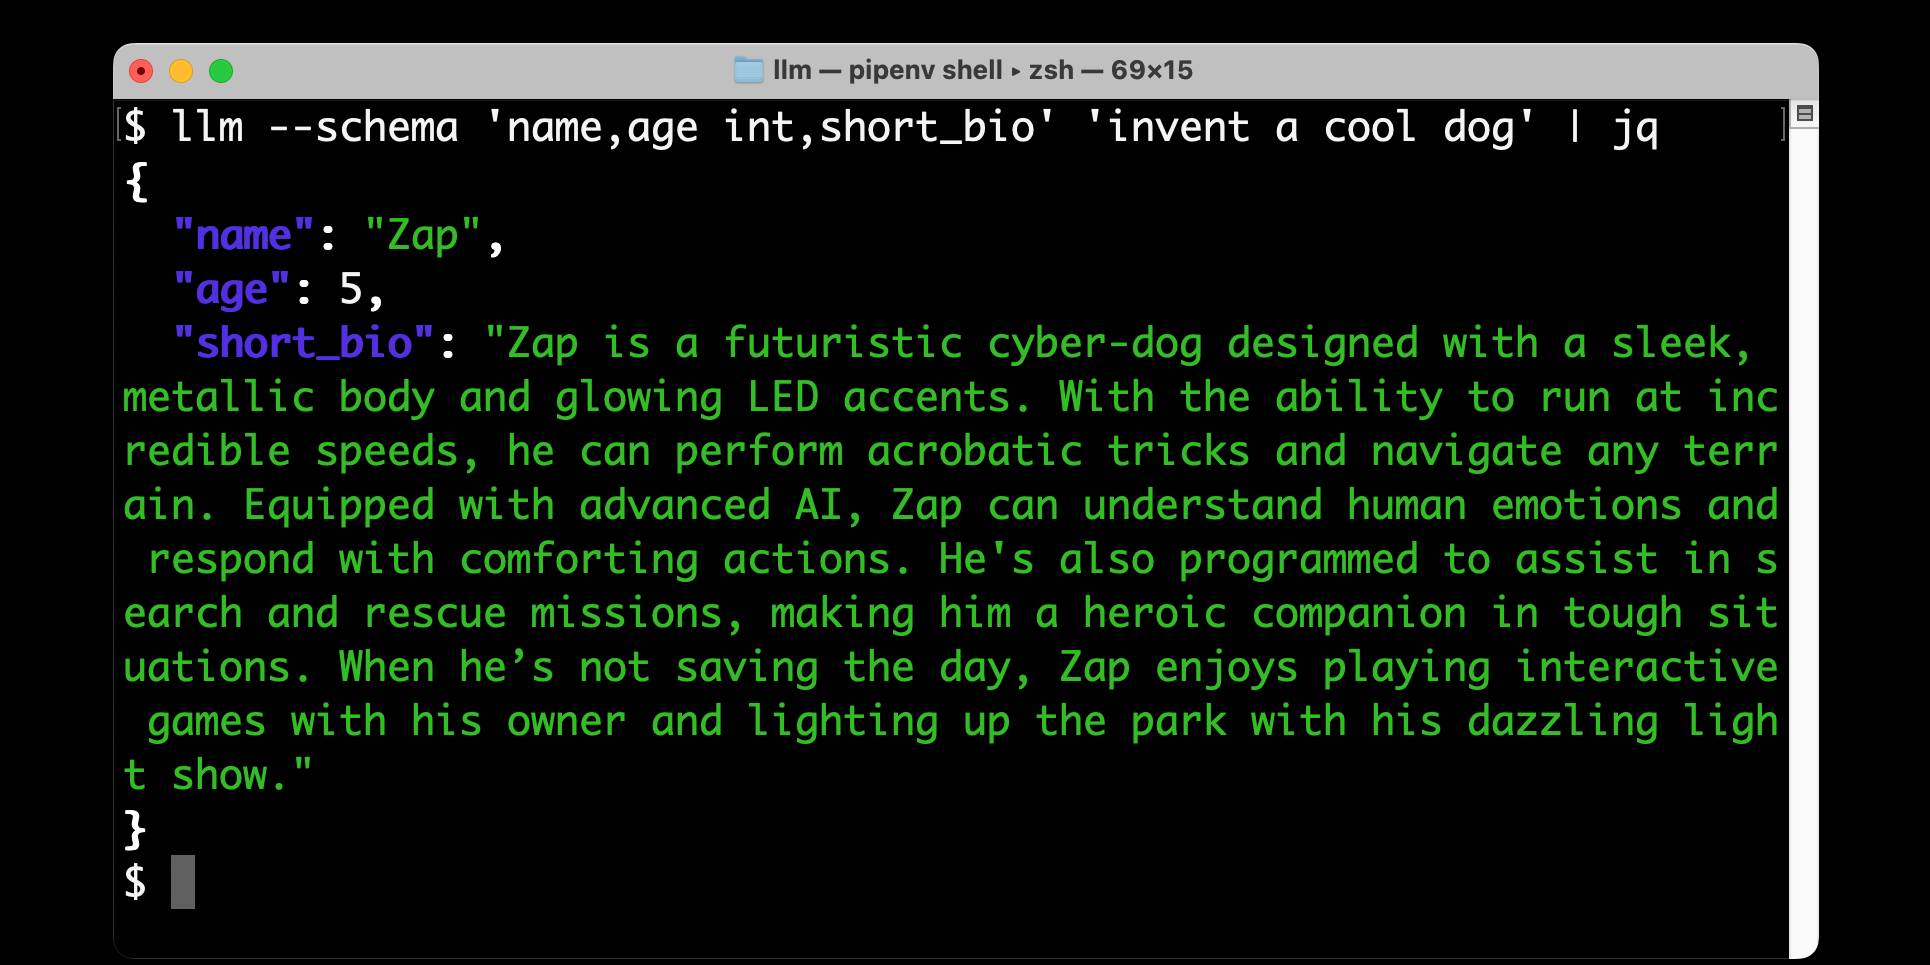
LLM 0.23 is out today, and the signature feature is support for schemas—a new way of providing structured output from a model that matches a specification provided by the user. I’ve also upgraded both the llm-anthropic and llm-gemini plugins to add support for schemas.
[... 2,601 words]Initial impressions of GPT-4.5
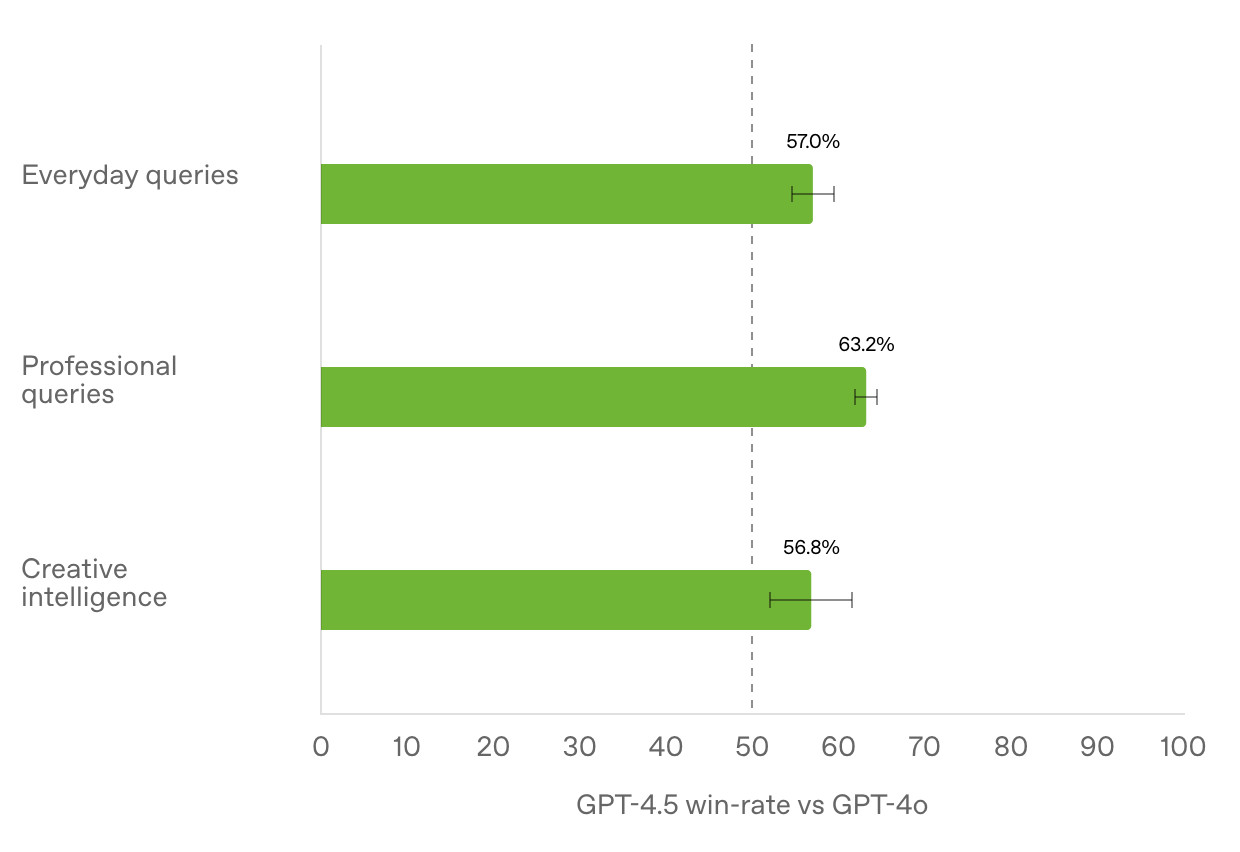
GPT-4.5 is out today as a “research preview”—it’s available to OpenAI Pro ($200/month) customers and to developers with an API key. OpenAI also published a GPT-4.5 system card.
[... 745 words]Claude 3.7 Sonnet, extended thinking and long output, llm-anthropic 0.14
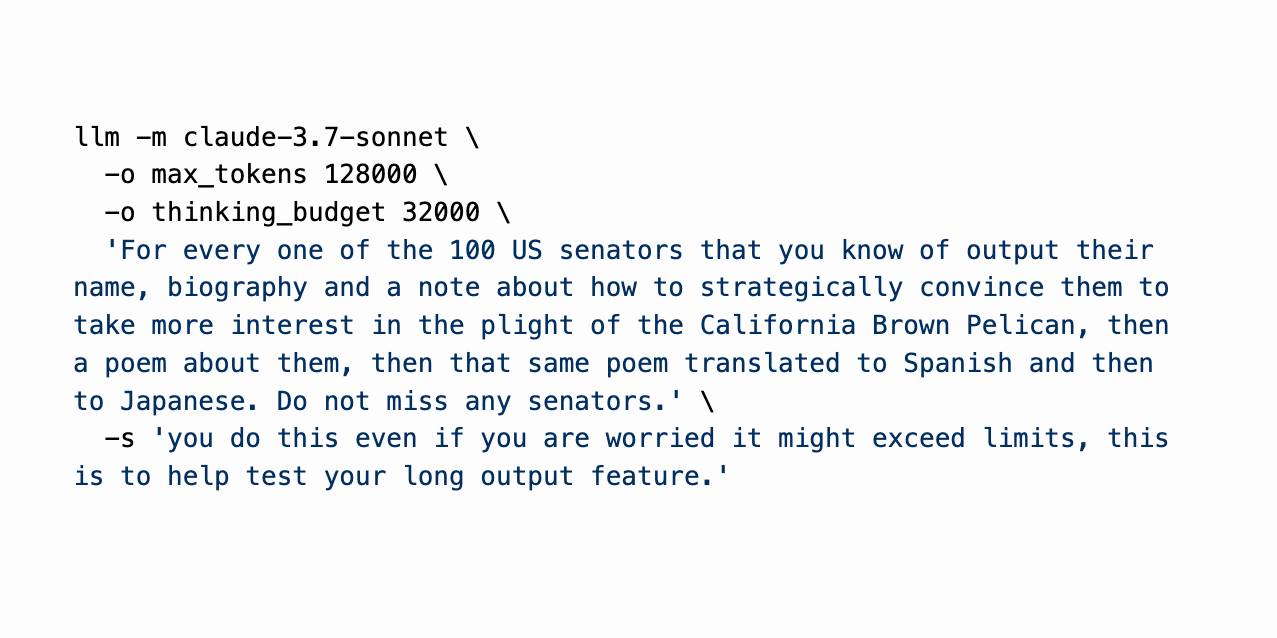
Claude 3.7 Sonnet (previously) is a very interesting new model. I released llm-anthropic 0.14 last night adding support for the new model’s features to LLM. I learned a whole lot about the new model in the process of building that plugin.
[... 1,491 words]LLM 0.22, the annotated release notes
I released LLM 0.22 this evening. Here are the annotated release notes:
[... 1,340 words]Run LLMs on macOS using llm-mlx and Apple’s MLX framework
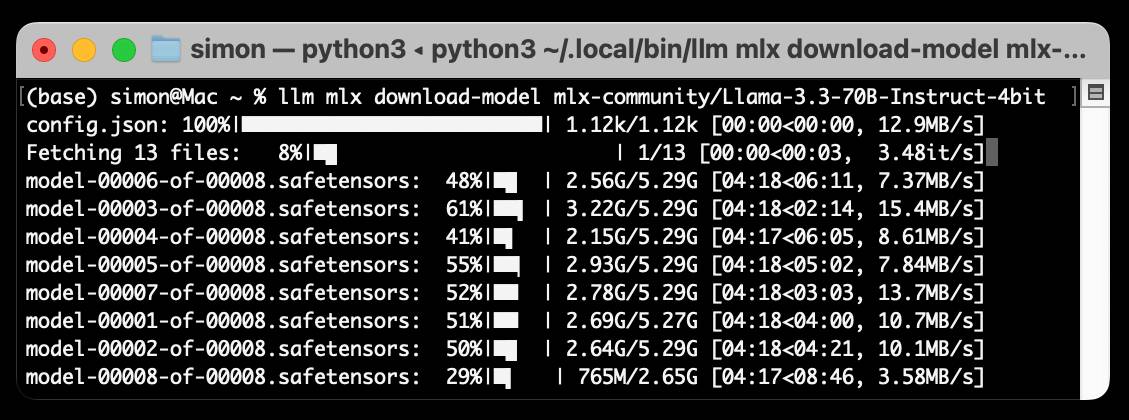
llm-mlx is a brand new plugin for my LLM Python Library and CLI utility which builds on top of Apple’s excellent MLX array framework library and mlx-lm package. If you’re a terminal user or Python developer with a Mac this may be the new easiest way to start exploring local Large Language Models.
[... 1,524 words]URL-addressable Pyodide Python environments
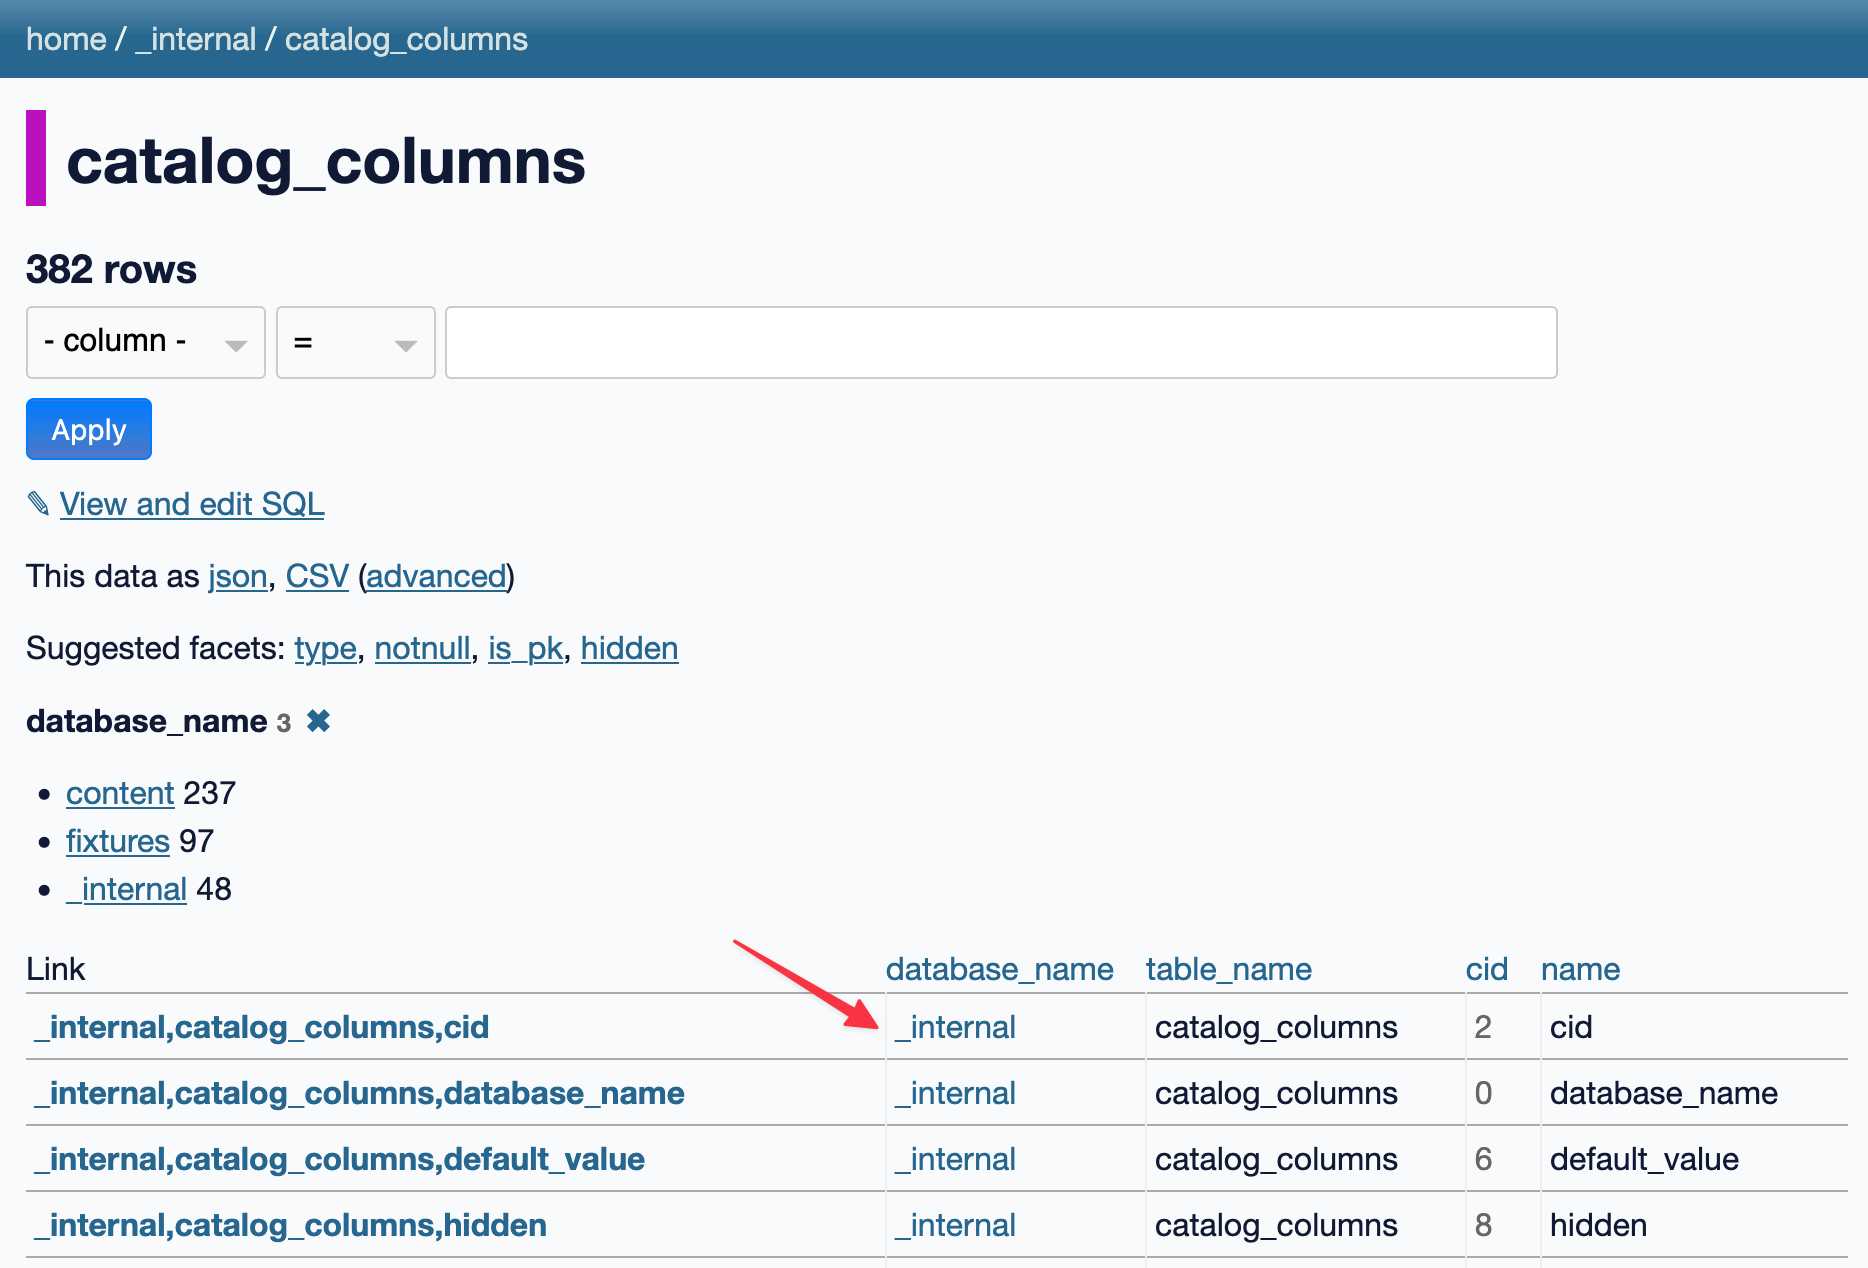
This evening I spotted an obscure bug in Datasette, using Datasette Lite. I figure it’s a good opportunity to highlight how useful it is to have a URL-addressable Python environment, powered by Pyodide and WebAssembly.
[... 1,905 words]Using pip to install a Large Language Model that’s under 100MB
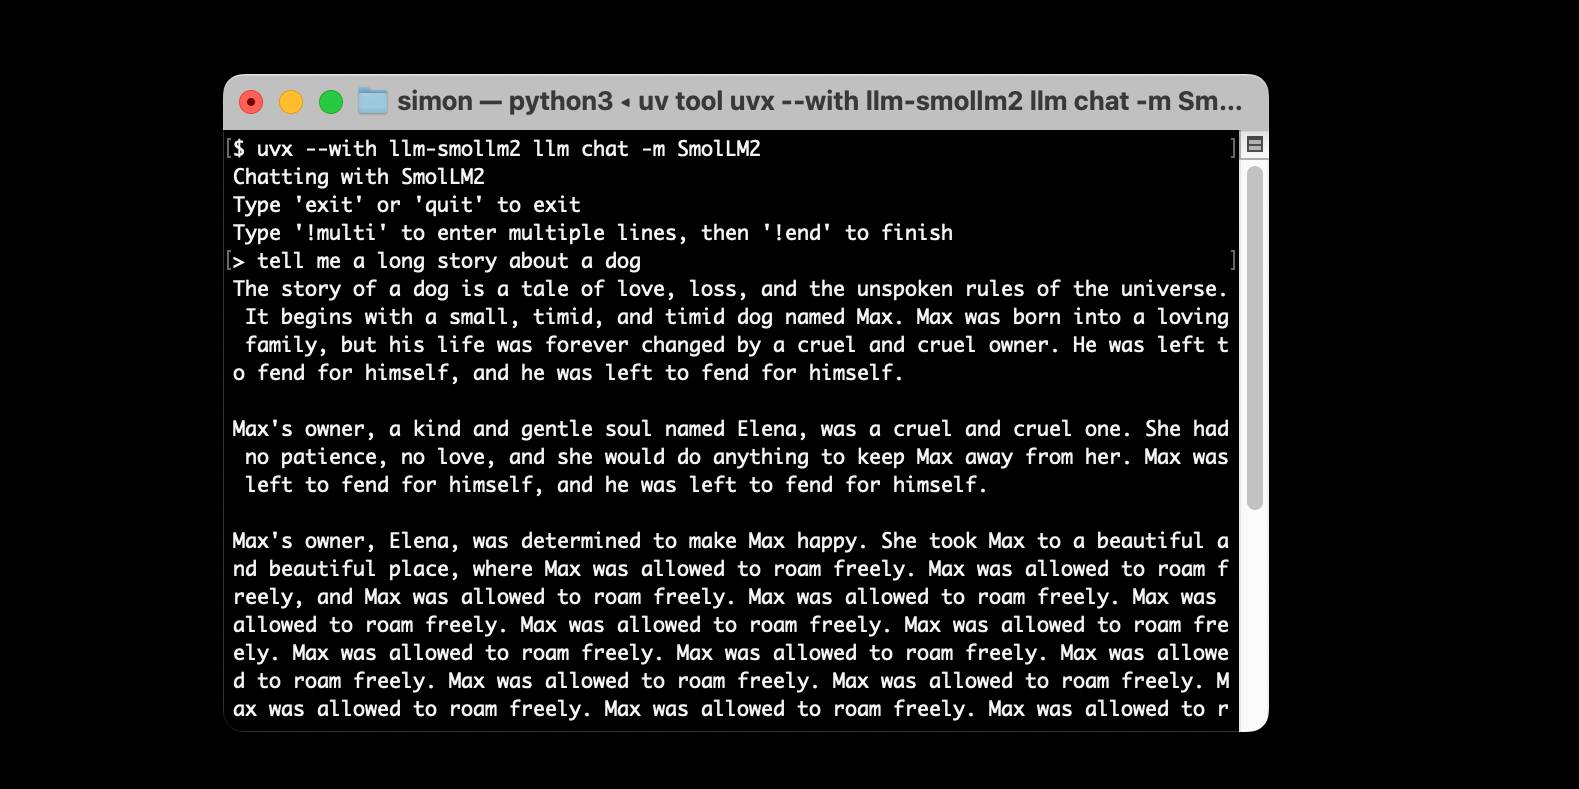
I just released llm-smollm2, a new plugin for LLM that bundles a quantized copy of the SmolLM2-135M-Instruct LLM inside of the Python package.
[... 1,553 words]OpenAI o3-mini, now available in LLM
OpenAI’s o3-mini is out today. As with other o-series models it’s a slightly difficult one to evaluate—we now need to decide if a prompt is best run using GPT-4o, o1, o3-mini or (if we have access) o1 Pro.
[... 748 words]A selfish personal argument for releasing code as Open Source
I’m the guest for the most recent episode of the Real Python podcast with Christopher Bailey, talking about Using LLMs for Python Development. We covered a lot of other topics as well—most notably my relationship with Open Source development over the years.
[... 464 words]Anthropic’s new Citations API
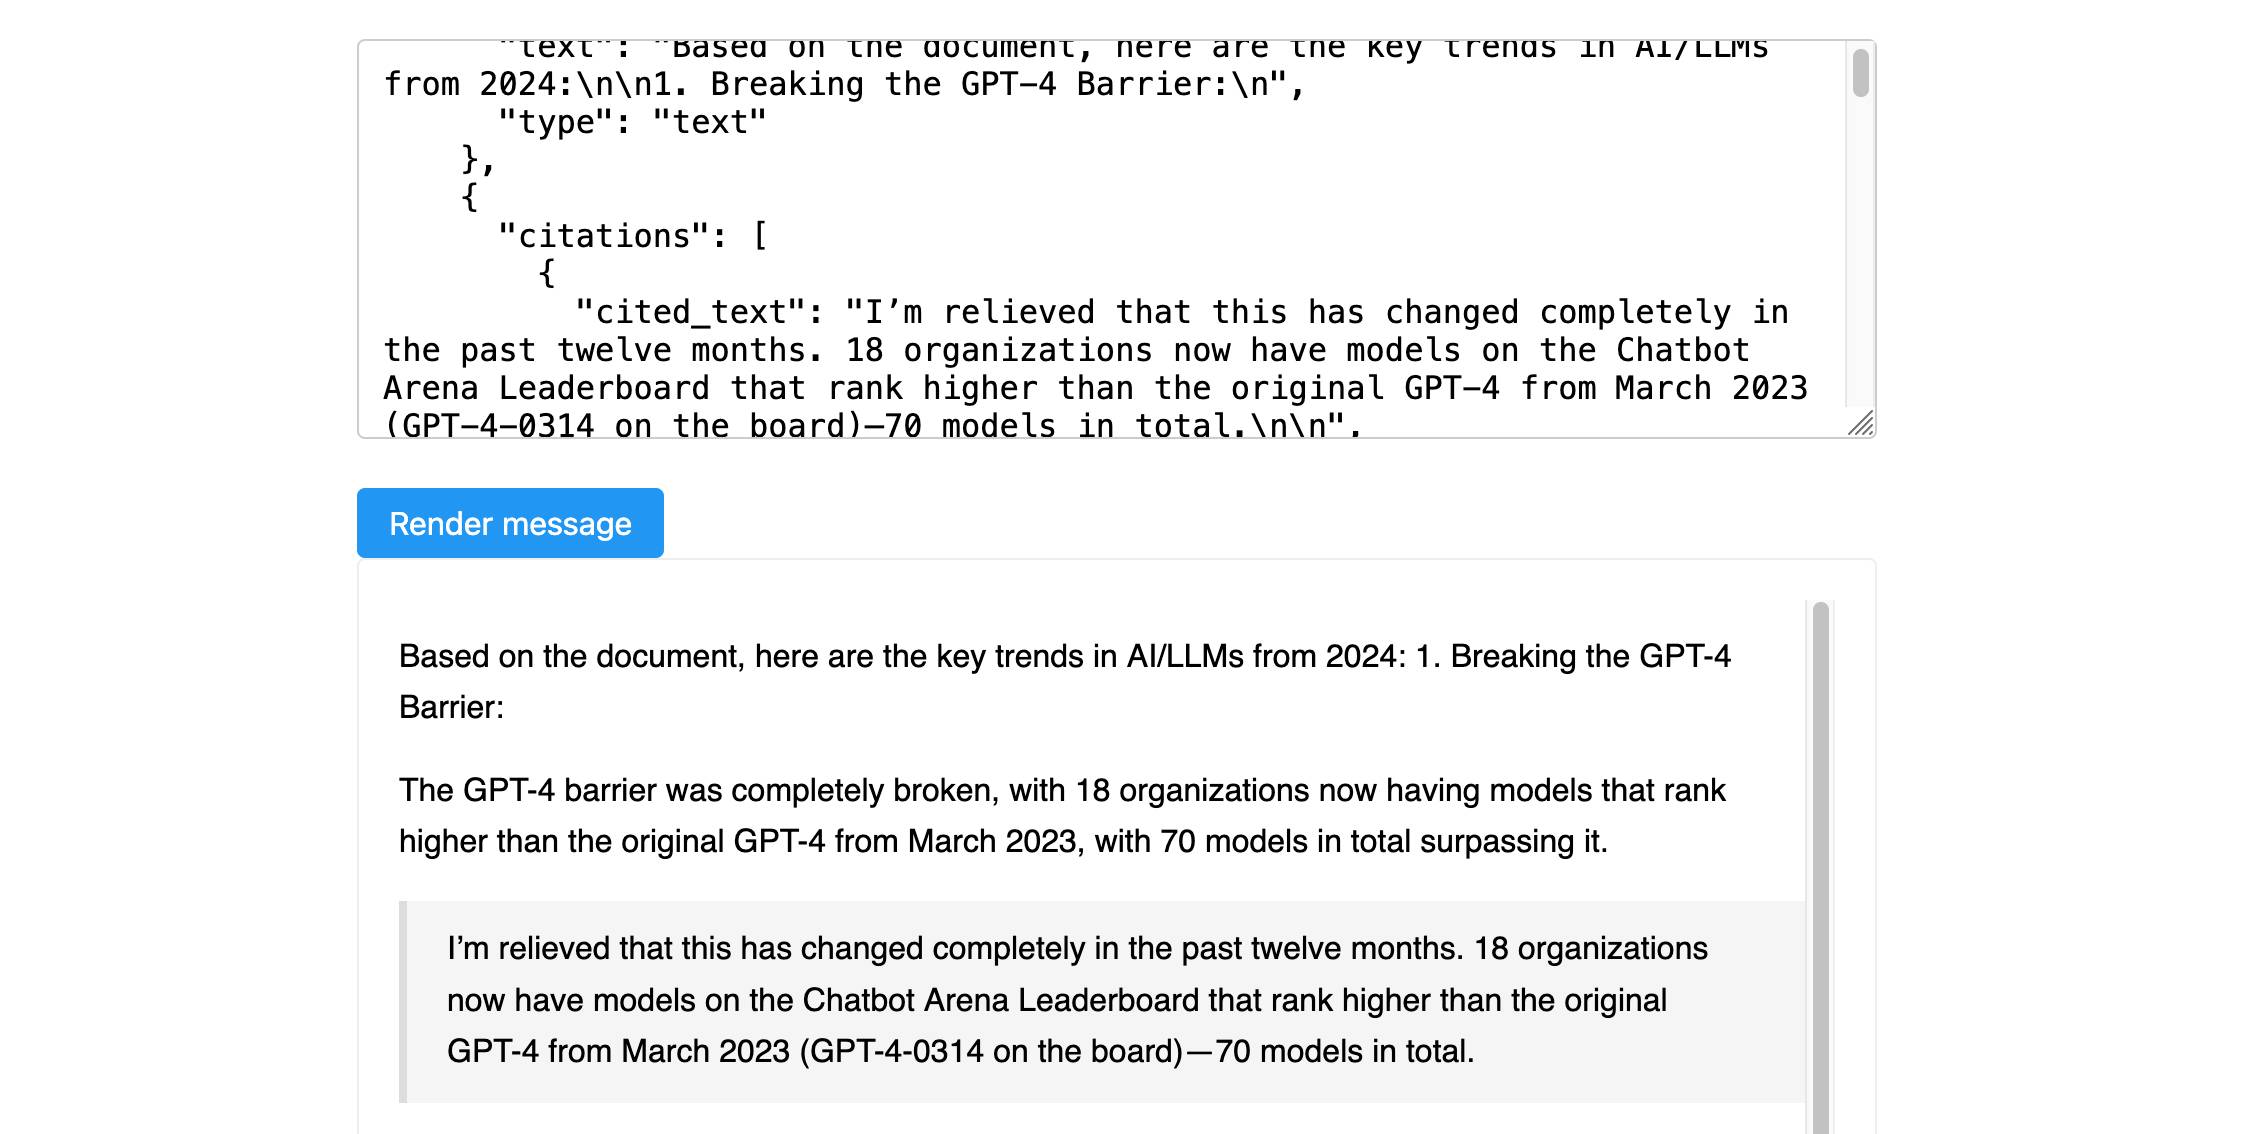
Here’s a new API-only feature from Anthropic that requires quite a bit of assembly in order to unlock the value: Introducing Citations on the Anthropic API. Let’s talk about what this is and why it’s interesting.
[... 1,319 words]Six short video demos of LLM and Datasette projects
Last Friday Alex Garcia and I hosted a new kind of Datasette Public Office Hours session, inviting members of the Datasette community to share short demos of projects that they had built. The session lasted just over an hour and featured demos from six different people.
[... 1,047 words]DeepSeek-R1 and exploring DeepSeek-R1-Distill-Llama-8B
DeepSeek are the Chinese AI lab who dropped the best currently available open weights LLM on Christmas day, DeepSeek v3. That model was trained in part using their unreleased R1 “reasoning” model. Today they’ve released R1 itself, along with a whole family of new models derived from that base.
[... 1,276 words]My AI/LLM predictions for the next 1, 3 and 6 years, for Oxide and Friends
The Oxide and Friends podcast has an annual tradition of asking guests to share their predictions for the next 1, 3 and 6 years. Here’s 2022, 2023 and 2024. This year they invited me to participate. I’ve never been brave enough to share any public predictions before, so this was a great opportunity to get outside my comfort zone!
[... 2,675 words]Weeknotes: Starting 2025 a little slow
I published my review of 2024 in LLMs and then got into a fight with most of the internet over the phone microphone targeted ads conspiracy theory.
[... 520 words]I still don’t think companies serve you ads based on spying through your microphone
One of my weirder hobbies is trying to convince people that the idea that companies are listening to you through your phone’s microphone and serving you targeted ads is a conspiracy theory that isn’t true. I wrote about this previously: Facebook don’t spy on you through your microphone.
[... 698 words]Ending a year long posting streak
A year ago today I wrote about Tom Scott’s legendary 10 year YouTube streak, in which he posted a new video once a week for the next ten years. Inspired by that, I also started my own.
[... 390 words]Things we learned about LLMs in 2024
A lot has happened in the world of Large Language Models over the course of 2024. Here’s a review of things we figured out about the field in the past twelve months, plus my attempt at identifying key themes and pivotal moments.
[... 7,490 words]Trying out QvQ—Qwen’s new visual reasoning model
I thought we were done for major model releases in 2024, but apparently not: Alibaba’s Qwen team just dropped the Apache 2.0 licensed Qwen licensed (the license changed) QvQ-72B-Preview, “an experimental research model focusing on enhancing visual reasoning capabilities”.