“hy3” in posts
Sorted by relevance · date
tencent/Hy3. New Apache 2.0 licensed model from Tencent in China:
Hy3 is a 295B-parameter Mixture-of-Experts (MoE) model with 21B active parameters and 3.8B MTP layer parameters, developed by the Tencent Hy Team. Following the Hy3 Preview launch in late April, we gathered feedback from 50+ products and scaled up post-training with higher quality data. Today, we introduce Hy3, which outperforms similar-size models and rivals flagship open-source models with 2-5x parameters. It also shows significant gains in utility across various products and productivity tasks.
The full-sized model is 598GB on Hugging Face, and the FP8 quantized one is 300GB. The context length is 256K.
It's available for free on OpenRouter until July 21st. I had it "Generate an SVG of a pelican riding a bicycle" there and got this:
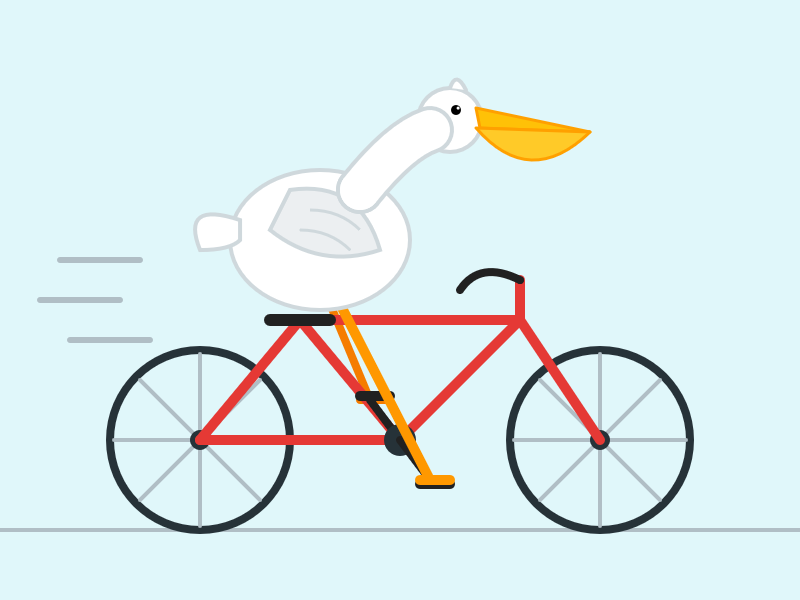
Update: I'd forgotten about this but Max Woolf wrote about an earlier preview of this model back on May 26th: The mysterious Hy3 LLM is topping OpenRouter Model Rankings by a large margin. When I tried that one I got back this pelican which wasn't as good as today's but did have a "Change Pelican Color" button, a first from any model.
Introducing Hy4 Preview. New open weight text input (no vision) LLM from Chinese company Tencent today: 770B total parameters, 49B active parameters, 1M token context window, 1.56TB on Hugging Face.
This is a big size increase from their previous Hy3 in July, which was 295B, 21B active, 256,000 context, 598GB.
I recently started using model chat templates to better understand their capabilities. Here's Hy4's chat_template.jinja on Hugging Face, which includes this section:
{%- if not reasoning_effort is defined %}
    {%- set reasoning_effort = 'high' %}
{%- elif reasoning_effort not in ['high', 'no_think'] %}
    {%- if reasoning_effort is none %}
        {{- raise_exception('reasoning_effort error : None, should be no_think/high') }}
    {%- else %}
        {{- raise_exception('reasoning_effort error : ' + reasoning_effort + ', should be no_think/high') }}
    {%- endif %}
{%- endif %}
So it looks like there are just two reasoning effort levels: "high" (the default) and "no_think" (reason by disabled).
I tried my "Generate an SVG of a pelican riding a bicycle" prompt with the default high reasoning via OpenRouter and got this:
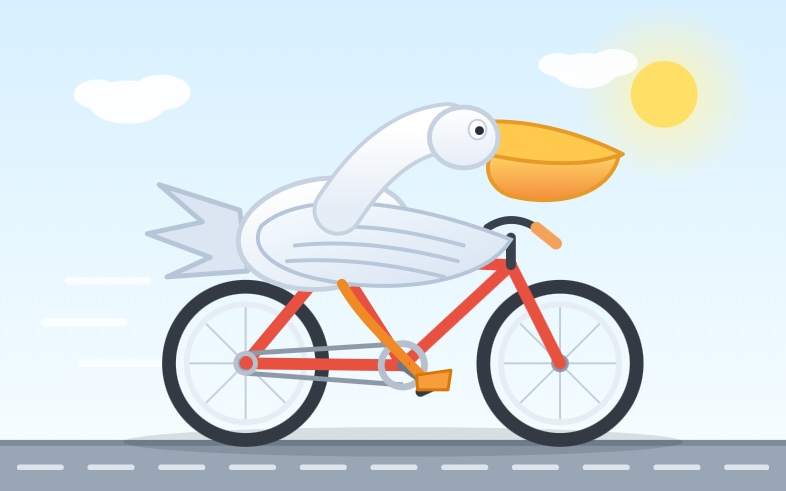
Quoting the reasoning trace:
[...] Let's maybe add a helmet? It could improve riding theme, but may obscure head. Maybe a small cycling cap or helmet? The user didn't ask; can add red helmet? Might be cute. But pelican with big beak; a helmet might obscure. Better maybe no.
Maybe add sunglasses? no.
Maybe add water? no.
It's interesting how the reasoning trace uses slightly truncated English, presumably because perfect grammar isn't useful or token efficient for hidden reasoning text.