15 posts tagged “migrations”
Migrating software architecture from one solution to another. Not the same thing as schema-migrations.
2026
Redesigning source control at Anthropic (via) Interesting piece from Anthropic describing why and how they built their own custom alternative to Git, based on the dramatic increase in rate of changes to their code after the past six months.
In May 2026, Anthropic averaged around 2,500 code changes merged per day; as of September, we merged over 30,000 per day.
They included a chart showing those changes. I had Claude modify their chart (code here) to add markers for the public releases of each of their models in 2026:
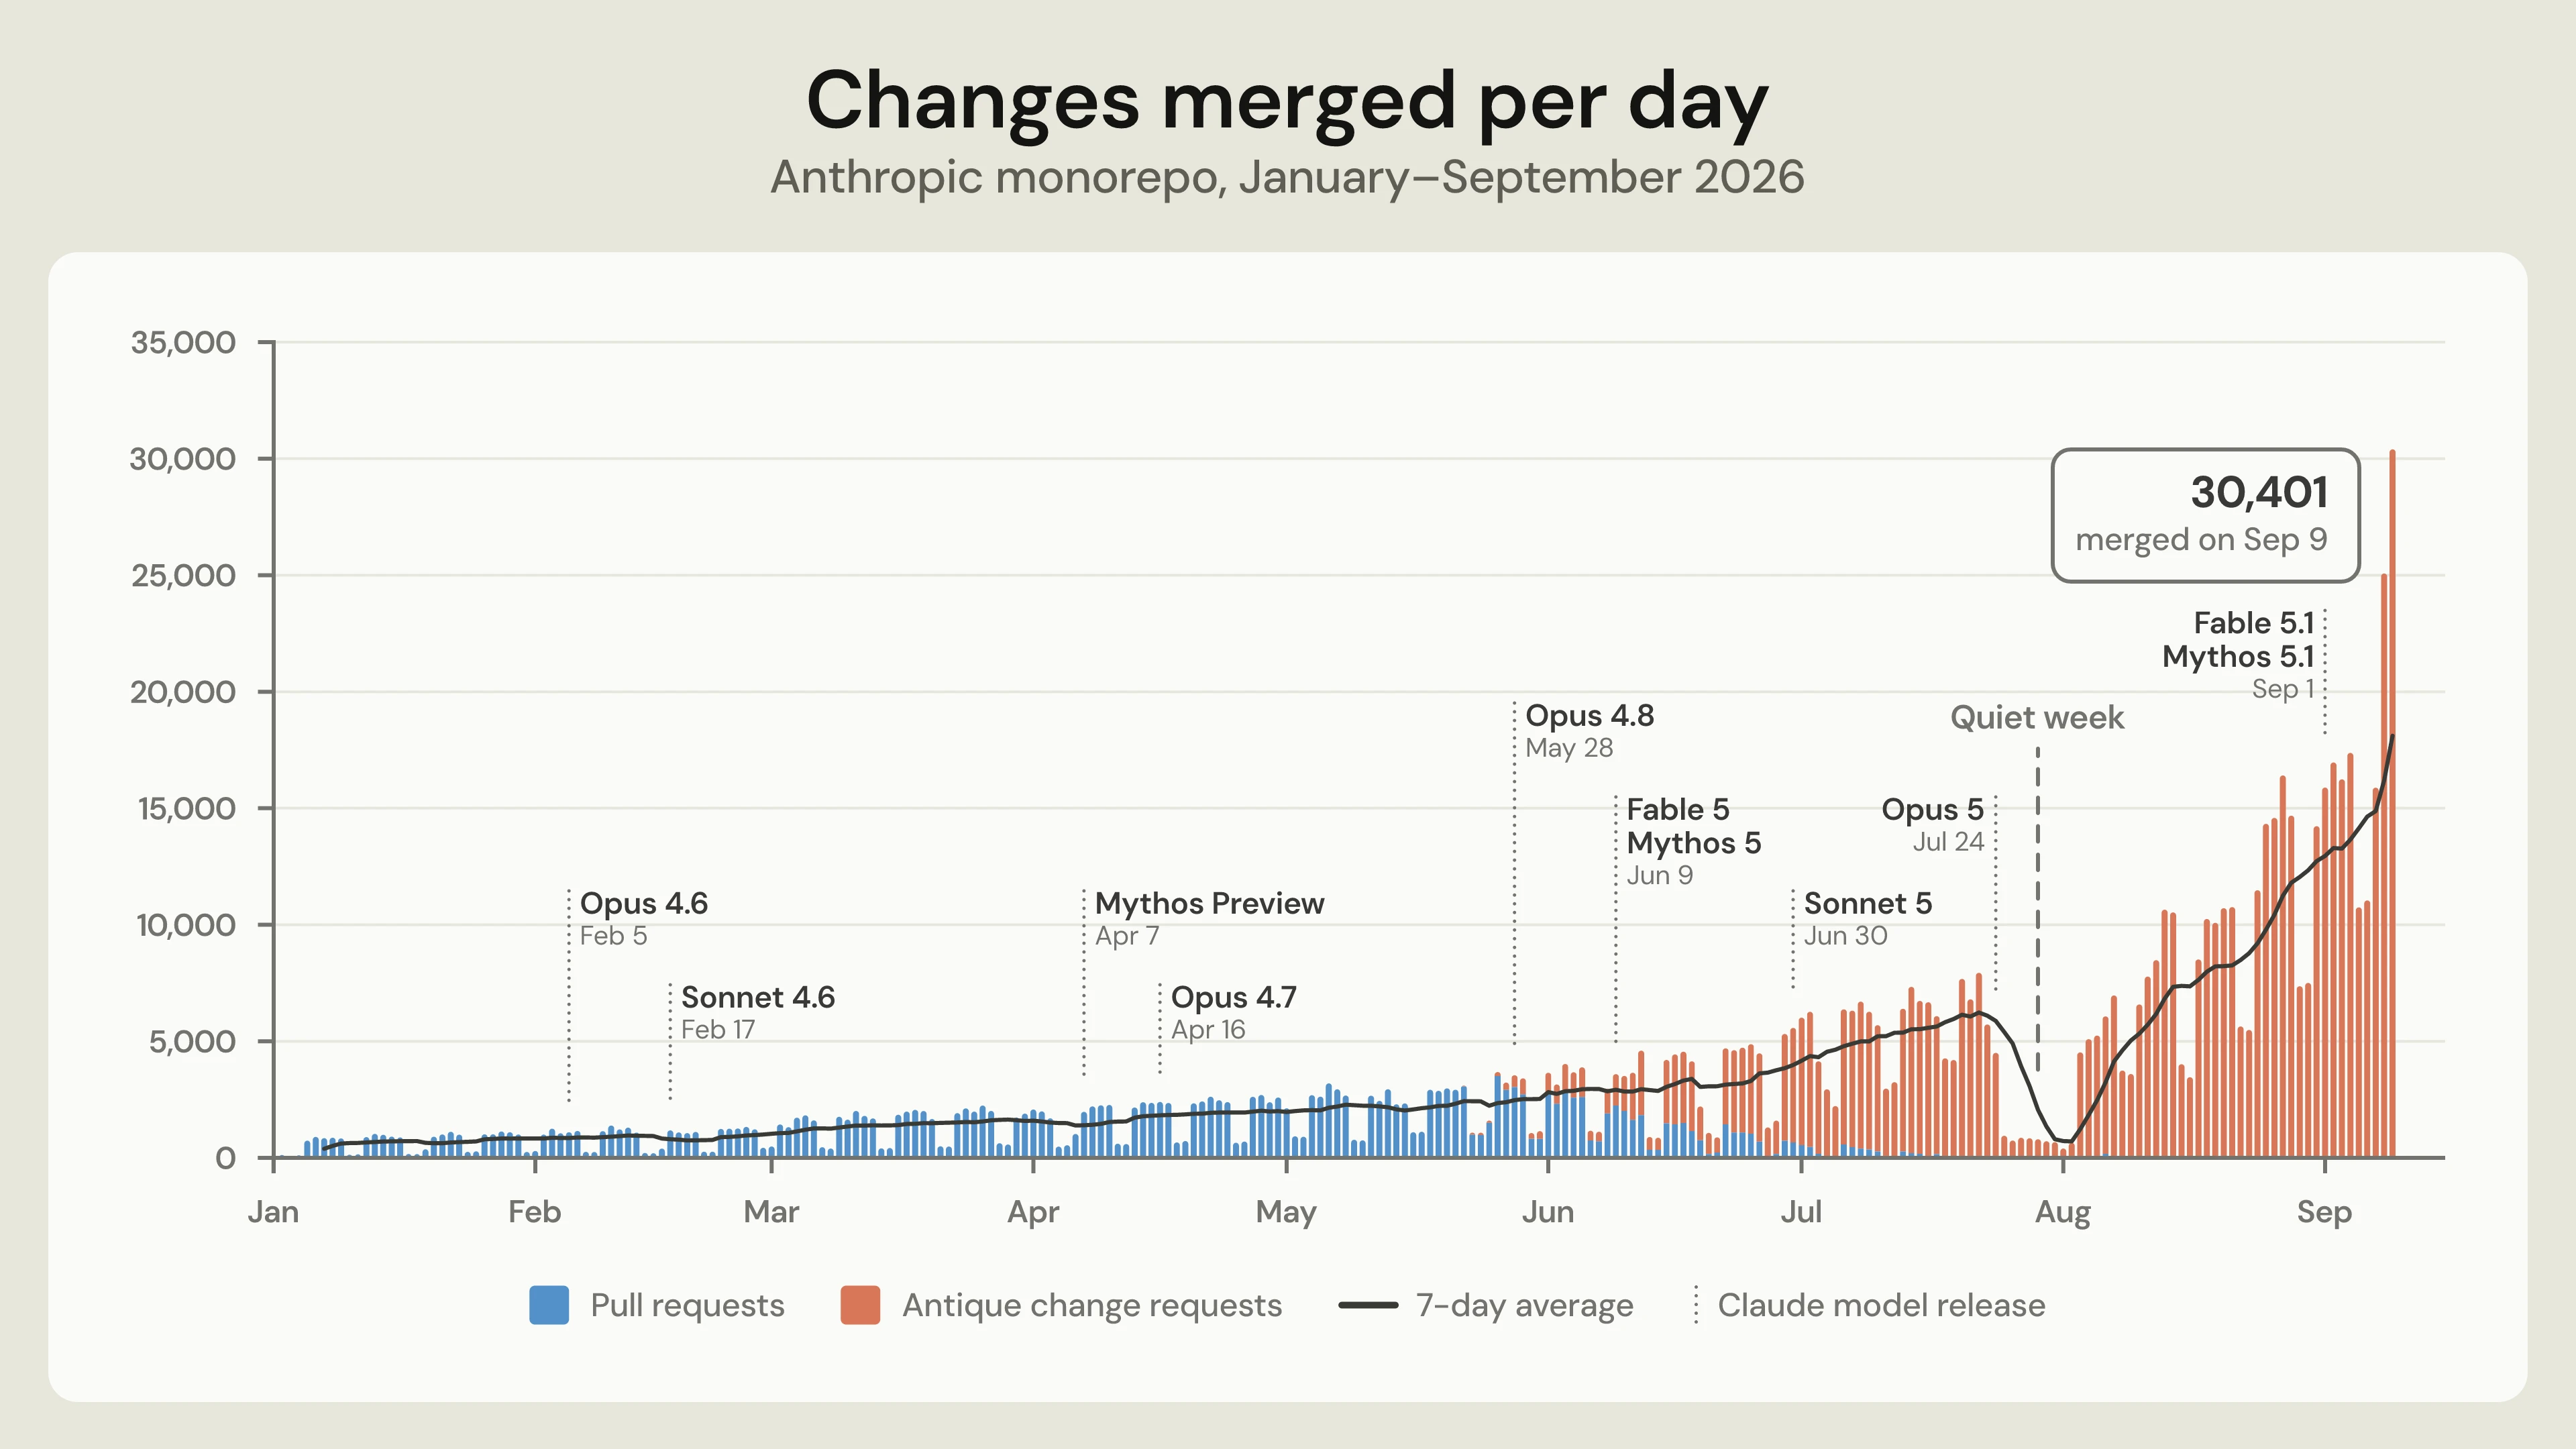
This shows public release dates, not the date when models became available for Anthropic's internal use. My guess is that the introduction of Fable/Mythos class models is a key factor in the increased coding velocity.
"Antique" is their new code review system. The source control system is called Scion, and sounds to me like a reinvention of centralized source control along the lines of Subversion.
(Update: Anthropic credit Google's Piper and Meta's Sapling as "prior art" - it looks like the core concept of "derived data" was heavily inspired by Mononoke, the server component of Sapling.)
They had some pretty extreme requirements:
The history of our main branch alone is almost 100 GB, and a compressed working copy is over 25 GB. We perform on the order of 25 million code checkouts per day for CI, before counting developer environments, agent sandboxes, and research jobs. Fetched naively, that would be over 600 PB of git traffic per day.
The new system was built by a team of seven people, and the migration from Git was completed in five months.
When asked on Hacker News about the lack of offline support, Scion engineer Nick G replied:
Since Claude is by far the heaviest user of Scion and is necessarily online, this just wasn't important to do.
As an aside, I've been trying adversarial review in my own projects recently, where you have a model try and find flaws (I often play Claude and GPT off against each other). This note from the article reflected my own experience with that:
Anthropic also makes extensive use of adversarial review, and, while this is incredibly effective in many ways, it can also be myopic, so skilled engineers needed to steer Claude away from over-engineering parts of the system in response to hypothetical concerns.
EVE Online: The Move to Python 3 Begins! (via) EVE Online has been one of the most interesting case studies in Python at scale for over twenty years now.
They've been running on Stackless Python since their launch in 2003, and their last major upgrade was 16 years ago, to Stackless Python 2.7 in 2010.
Their upgrade to Python 3 will start using the futurize script against 2.4 million lines of code, followed by careful manual review of the ~20,000 places where Python 2 and 3 behavior differ - for example 1 / 2 is 0 in Python 2 but is 0.5 in Python 3.
There's nothing in this announcement about how they plan to replace Stackless, but at their conference last year they presented Scheduling in Carbon: Leaving Stackless Python Behind describing how they replaced Stackless in the Carbon engine for their more recent game EVE Frontier, using their (now open source) carbonengine/scheduler library.
lobste.rs is now running on SQLite. Community site Lobsters has been planning a migration away from MariaDB since August 2018 - originally targeting PostgreSQL, but last year they decided to investigate SQLite instead.
This weekend they completed the migration, and now consider it stable enough that it looks like this is the permanent architecture for the site going forward:
SQLite seems to have passed with flying colors: cpu usage is down, memory usage is down, site seems to be snappier at least for me, 1/2 the vps cost once mariadb vps is taken down
The Lobsters Rails application now runs on a single VPS, with a primary content SQLite database file that's around 3.8GB. There's also a 1.1GB cache database, a 218MB queue database, and a still growing 555MB rack_attack database used by the Rack::Attack middleware for blocking and throttling abusive requests.
There are plenty more details in both the linked thread and this SQLite migration PR by Thomas Dziedzic, which added 735 lines and removed 593 lines across 30 commits and 188 files. That PR built on top of previous PRs #1705, #1871, and #1924.
This is a really useful case study, and a great reminder that you can get a whole lot done with a single server and SQLite in 2026.
With enough users, every observable behavior becomes a dependency - regardless of what you promised. Someone is scraping your API, automating your quirks, caching your bugs.
This creates a career-level insight: you can’t treat compatibility work as “maintenance” and new features as “real work.” Compatibility is product.
Design your deprecations as migrations with time, tooling, and empathy. Most “API design” is actually “API retirement.”
— Addy Osmani, 21 lessons from 14 years at Google
2024
In the past, these decisions were so consequential, they were basically one-way doors, in Amazon language. That’s why we call them ‘architectural decisions!’ You basically have to live with your choice of database, authentication, JavaScript UI framework, almost forever.
But that’s changing with LLMs, because you can explore, investigate, and even prototype each one so quickly. Even technology migrations are becoming so much easier/cheaper/faster.
These are all examples of increasing optionality.
— Steve Yegge, via Gene Kim
Migrations are not something you can do rarely, or put off, or avoid; not if you are a growing company. Migrations are an ordinary fact of life.
Doing them swiftly, efficiently, and -- most of all -- completely is one of the most critical skills you can develop as a team.
Before Google Reader was shut down, they were internally looking for maintainers. It turned out you have to deal with three years of infra migrations if you sign up to be the new owner of Reader. No one wanted that kind of job for a product that is not likely to grow 10x.
2023
Stripe: Online migrations at scale (via) This 2017 blog entry from Jacqueline Xu at Stripe provides a very clear description of the “dual writes” pattern for applying complex data migrations without downtime: dual write to new and old tables, update the read paths, update the write paths and finally remove the now obsolete data—illustrated with an example of upgrading customers from having a single to multiple subscriptions.
2021
Porting VaccinateCA to Django
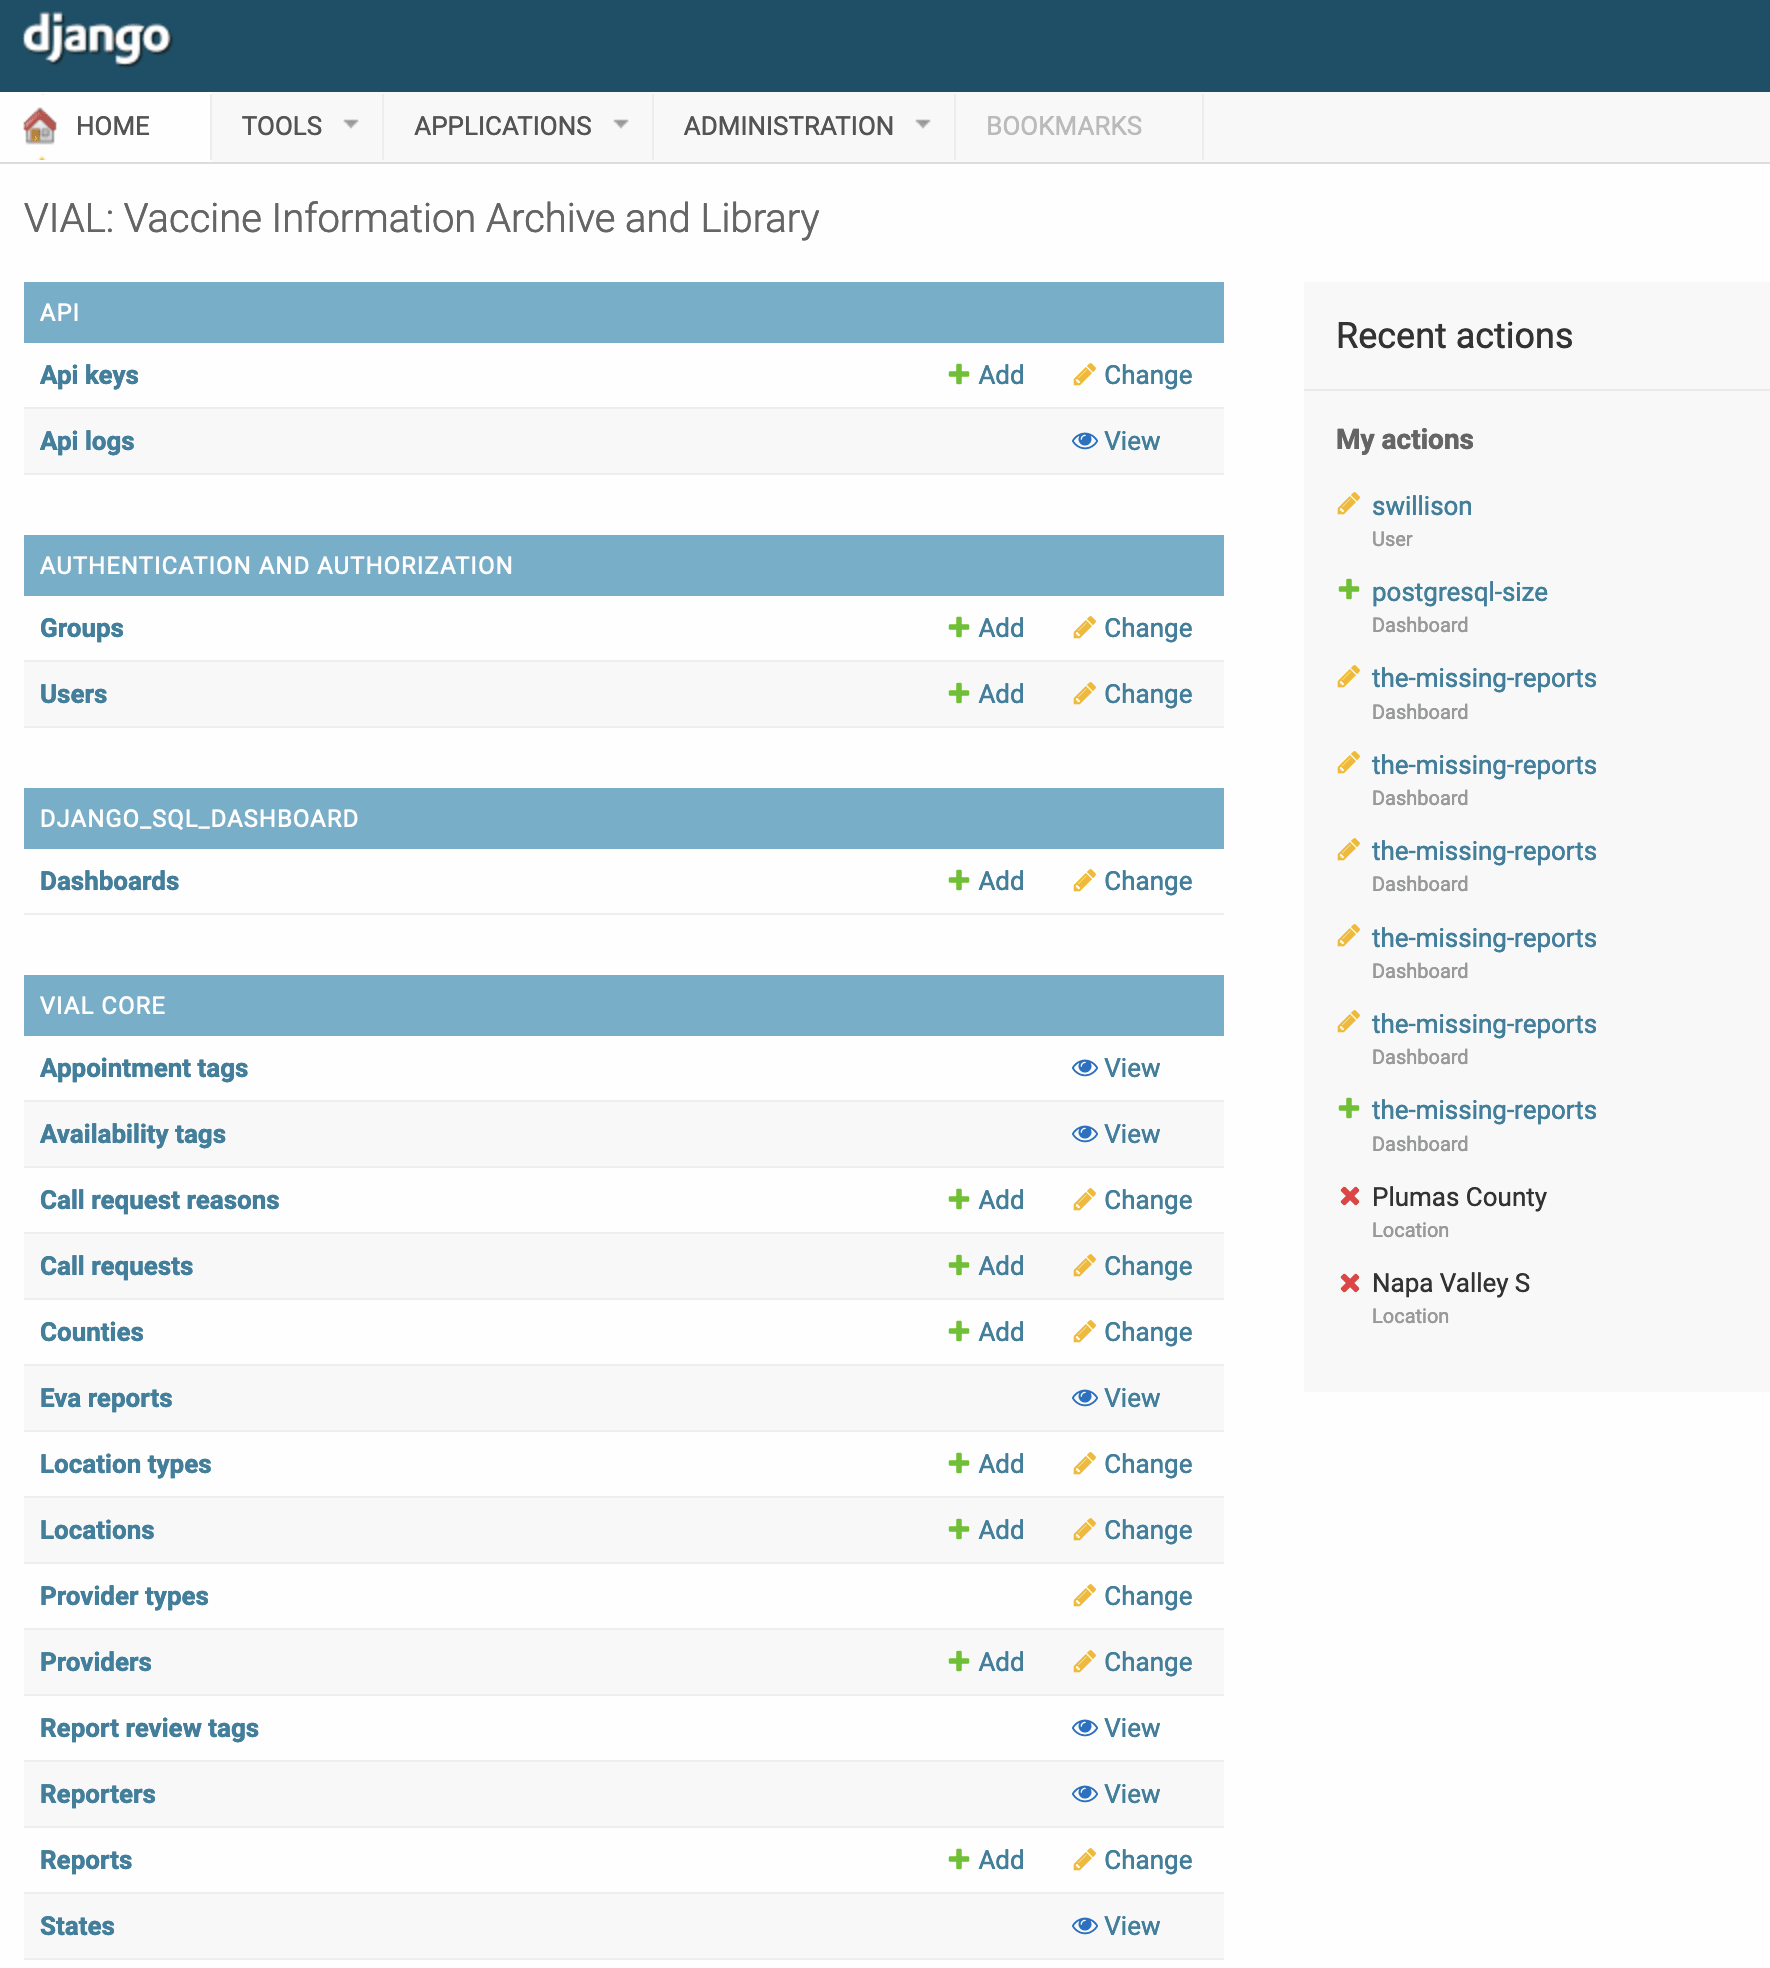
As I mentioned back in February, I’ve been working with the VaccinateCA project to try to bring the pandemic to an end a little earlier by helping gather as accurate a model as possible of where the Covid vaccine is available in California and how people can get it.
[... 2,157 words]2020
Why we at $FAMOUS_COMPANY Switched to $HYPED_TECHNOLOGY (via) Beautiful piece of writing by Saagar Jha. “Ultimately, however, our decision to switch was driven by our difficulty in hiring new talent for $UNREMARKABLE_LANGUAGE, despite it being taught in dozens of universities across the United States. Our blog posts on $PRACTICAL_OPEN_SOURCE_FRAMEWORK seemed to get fewer upvotes when posted on Reddit as well, cementing our conviction that our technology stack was now legacy code.”
2018
How we rolled out one of the largest Python 3 migrations ever. “If you’re using Dropbox today, the application is powered by a Dropbox-customized variant of Python 3.5”
Migrating Messenger storage to optimize performance (via) Fascinating case-study of a truly gargantuan migration. Messenger has over a billion users, and Facebook successfully migrated its backend storage from HBase to their MyRocks database (a fork of MySQL with a storage engine built on their SSD-optimized RocksDB key/value library) without any user-visible downtime. They ended up using two migration paths: one for the 99.9% of regular accounts, and a separate path for extremely high volume accounts (businesses with very active chat bots or support systems).
Migrations are both essential and frustratingly frequent as your codebase ages and your business grows: most tools and processes only support about one order of magnitude of growth before becoming ineffective, so rapid growth makes them a way of life. [...] As a result you switch tools a lot, and your ability to migrate to new software can easily become the defining constraint for your overall velocity. [...] Migrations matter because they are usually the only available avenue to make meaningful progress on technical debt.
— Will Larson, Migrations: the sole scalable fix to tech debt.
2017
Porting my blog to Python 3
This blog is now running on Python 3! Admittedly this is nearly nine years after the first release of Python 3.0, but it’s the first Python 3 project I’ve deployed myself so I’m pretty excited about it.
[... 883 words]
Comment My comment on There's No Limit to How Bad Code Can Get — Lobste.rs
[In reply to a comment about burning it down to start from scratch when technical debt becomes overwhelming]
In my experience it's so rare for that to work.
You announce the old thing is irrecoverably drowning in tech debt. You spin up a team to rewrite it from scratch. Work begins.
Meanwhile the old thing remains a moving target: it's running the core business, so changes are still necessary. The developers working on it know that it's going to be made obsolete by the new thing soon, so they don't have any incentive to go beyond the smallest effort possible to add the new features. Technical debt continues to mount.
Meanwhile, the team working on the new thing are ambitious and probably a little naive. They start out at a great pace - it's greenfield after all - but as time progresses it becomes apparent that nobody fully understands the behavior and scope of the thing they are replacing. If it was well documented and tested it wouldn't need to be replaced, after all...
After months (or even years) without delivering value, the pressure is on to "ship it", so the new system is launched to handle a subset of what the old system handled - or often for some new feature that was too hard to build with the now mostly unmaintained old system.
... so now you have TWO systems in production - the janky old system that nobody wants to touch, and a new system which handles just a few production features and is 80% inactive code that is meant to replace the old system, eventually.
If you're really lucky the company won't have lost patience with the new system and will allow that work to continue. The longer this all takes, and the longer the old system stays in production and stubbornly continues to work, the higher the risk that "priorities have changed" and the new system total replacement work is abandoned, leaving you with two systems where you used to have one.
The best article I've read about completing this process responsibly is Migrations: the sole scalable fix to tech debt by Will Larson.
If I run into a situation like this in the future, my strong recommendation will be to shore up the old system with as much automated testing as possible and then seeing if targeted refactors can get it to the desired shape. My hunch is that in many cases that will have a much higher chance of success than the siren call of a greenfield replacement.
# 6th September 2026, 9:08 am / migrations, technical-debt